Publications

* Equal contribution · † Corresponding author

2026

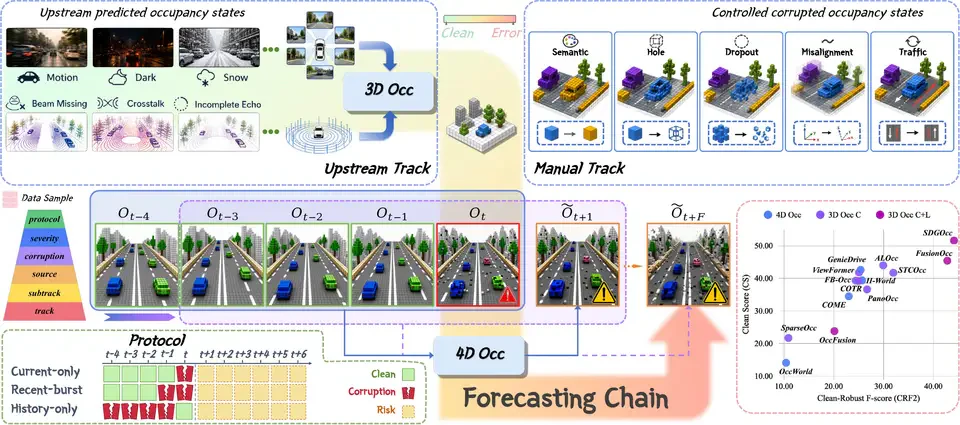
OccStress: Stress-Testing the 4D Occupancy Forecasting Chain — research illustration

OccStress: Stress-Testing the 4D Occupancy Forecasting Chain

Y. Zheng, J. Hu, J. Xiong, R. Liu, J. Zheng, K. Yang, J. Zhang†

NeurIPS 2026

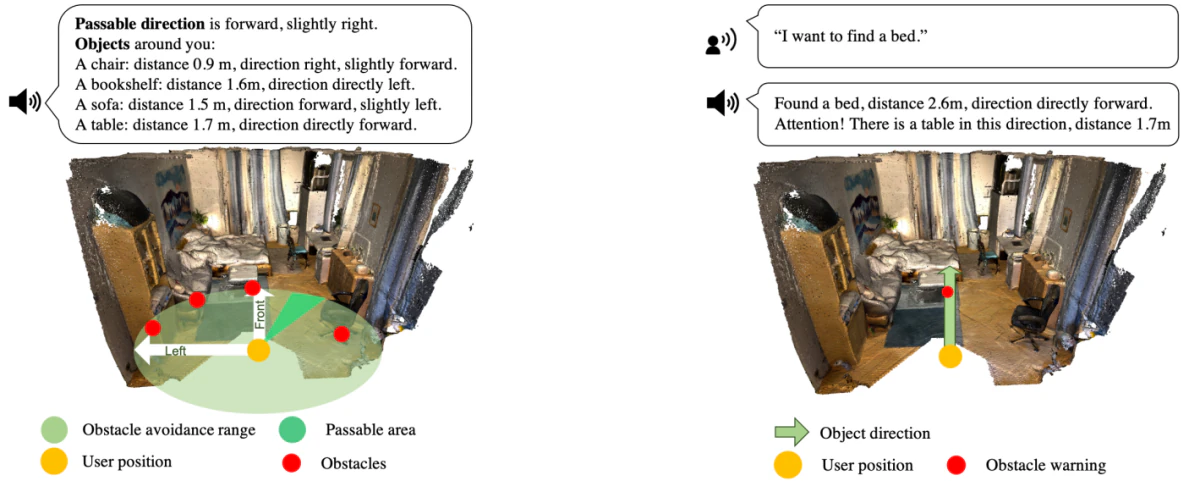
VLAN: Vision-Language Accessible Navigation

J. Hu, Y. Zheng, W. Wu, W. Feng, C. Cheng, J. Zhang†

NeurIPS 2026

Read, Parse, Describe: Unified Document Parsing with Visual Element Description Generation — research illustration

Read, Parse, Describe: Unified Document Parsing with Visual Element Description Generation

Y. Chen, Y. Chen, Z. Cai, R. Liu, J. Zheng, J. Wei, D. Wen, W. Fan, K. Peng, J. Zhang, R. Stiefelhagen

NeurIPS 2026

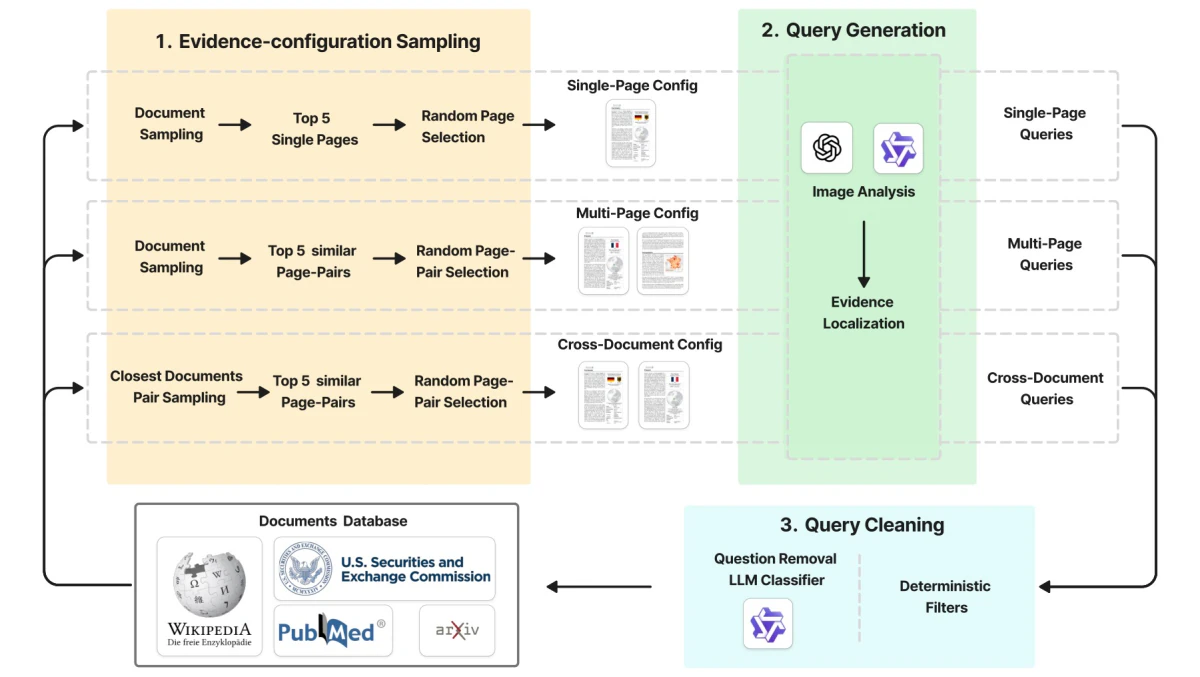
VL-DocIR: A Benchmark for Vision-Based Long Document Information Retrieval — research illustration

VL-DocIR: A Benchmark for Vision-Based Long Document Information Retrieval

S. Ott, Y. Chen, R. Liu, J. Zheng, J. Wei, D. Wen, K. Peng, J. Zhang, R. Stiefelhagen

NeurIPS 2026

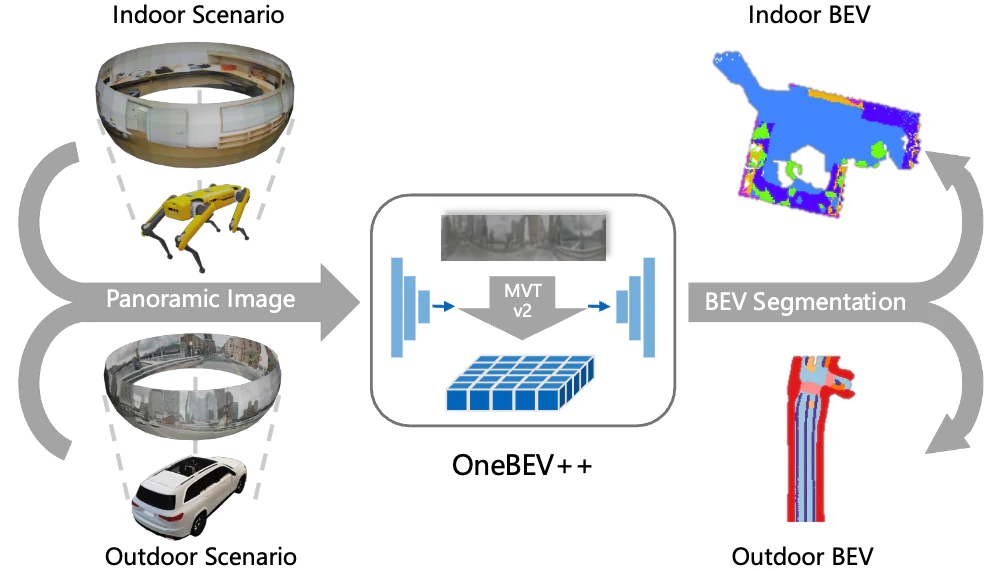
OneBEV++: Towards Unifying Bird’s-Eye-View Semantic Mapping with Panoramas — research illustration

OneBEV++: Towards Unifying Bird’s-Eye-View Semantic Mapping with Panoramas

J. Wei, Z. Teng, F. Teng, J. Zheng, R. Liu, Y. Chen, J. Hu, K. Yang, J. Zhang, R. Stiefelhagen

IEEE T-PAMI 2026

X²Localizer: Cross-grained Alignment for Progressive Cross-view Video Geo-localization — research illustration

X²Localizer: Cross-grained Alignment for Progressive Cross-view Video Geo-localization

Z. Zeng, W. Fan, Y. Chen, J. M. Goo, J. Zheng†, R. Liu, K. Peng, J. Zhang†, R. Stiefelhagen, J. Boehm

BMVC 2026 (🏆 Oral)

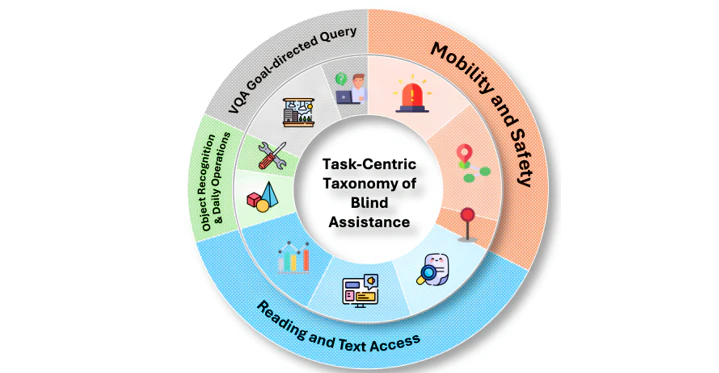
Position: Assistive Agents Need Accessibility Alignment — research illustration

Position: Assistive Agents Need Accessibility Alignment

J. Hu, C. Yan, Y. Zheng, Z. Wang, J. Zhang

ICML 2026 (🏆 Spotlight)

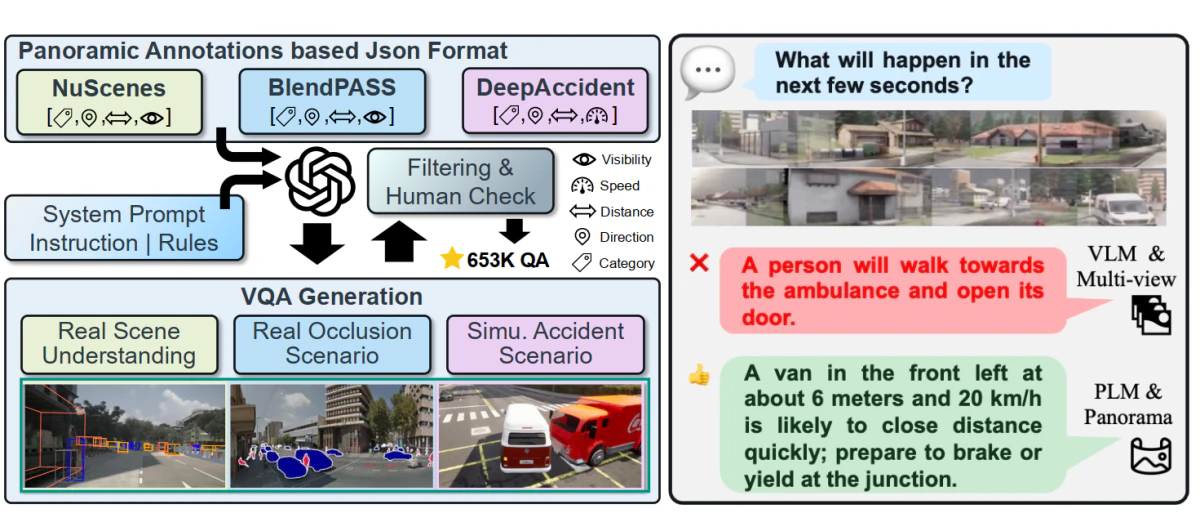
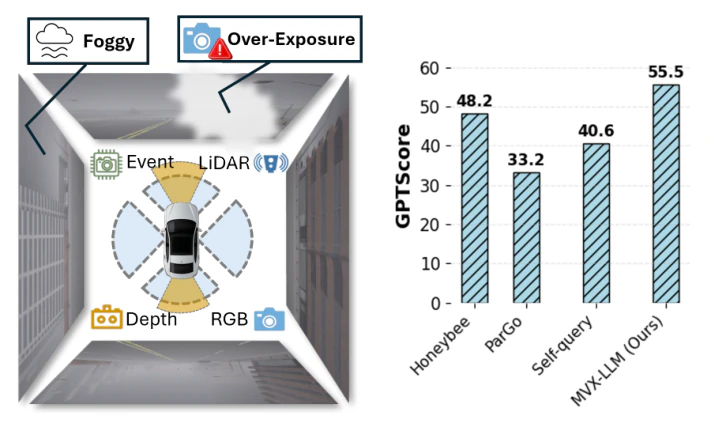
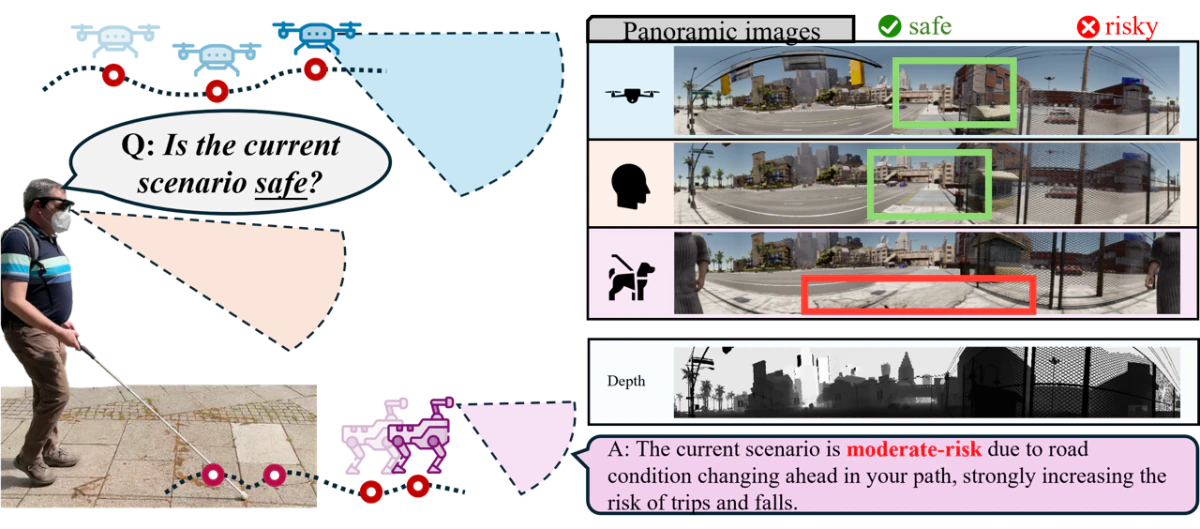
More than the Sum: Panorama-Language Models for Adverse Omni-Scenes — research illustration

More than the Sum: Panorama-Language Models for Adverse Omni-Scenes

W. Fan, R. Liu, J. Wei, Y. Chen, J. Zheng†, Z. Zeng, J. Zhang†, Q. Li, L. Shen, R. Stiefelhagen

CVPR 2026

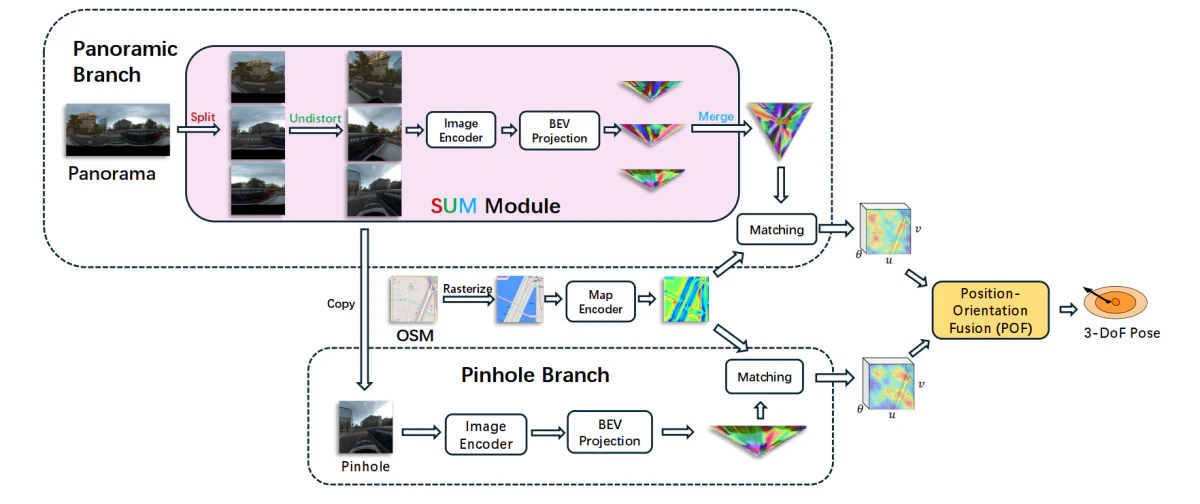
RHO: Robust Holistic OSM-Based Metric Cross-View Geo-Localization — research illustration

RHO: Robust Holistic OSM-Based Metric Cross-View Geo-Localization

J. Zheng*†, R. Dai*, R. Liu, Z. Zeng, Y. Chen, F. Wang, K. Peng, K. Yang, J. Zhang†, R. Stiefelhagen

CVPR 2026

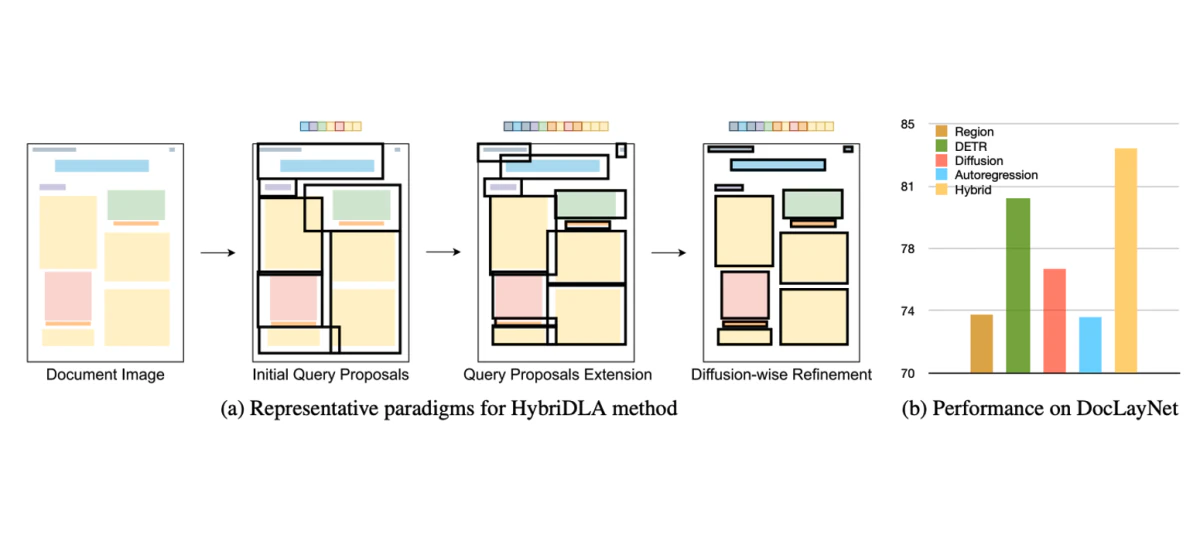
HybriDLA: Hybrid Generation for Document Layout Analysis — research illustration

HybriDLA: Hybrid Generation for Document Layout Analysis

Y. Chen, O. Moured, R. Liu, J. Zheng, K. Peng, J. Zhang†, R. Stiefelhagen

AAAI 2026 (🏆 Oral)

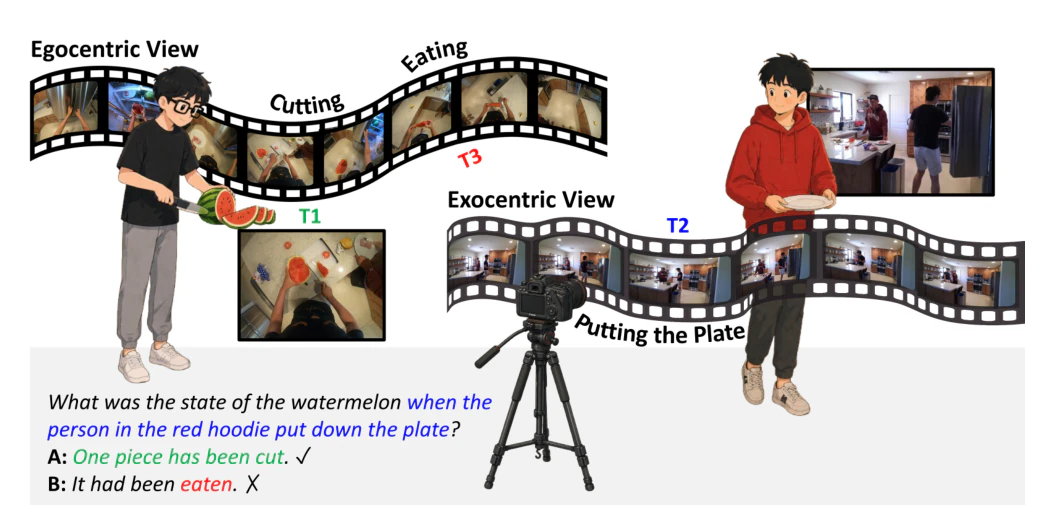
EgoExoMem: Cross-View Memory Reasoning over Synchronized Egocentric and Exocentric Videos — research illustration

EgoExoMem: Cross-View Memory Reasoning over Synchronized Egocentric and Exocentric Videos

R. Liu, J. Zheng, Y. Chen, D. Wen, S. Quan, C. Wu, J. Zhang, K. Yang, K. Peng, R. Stiefelhagen

arXiv preprint 2026

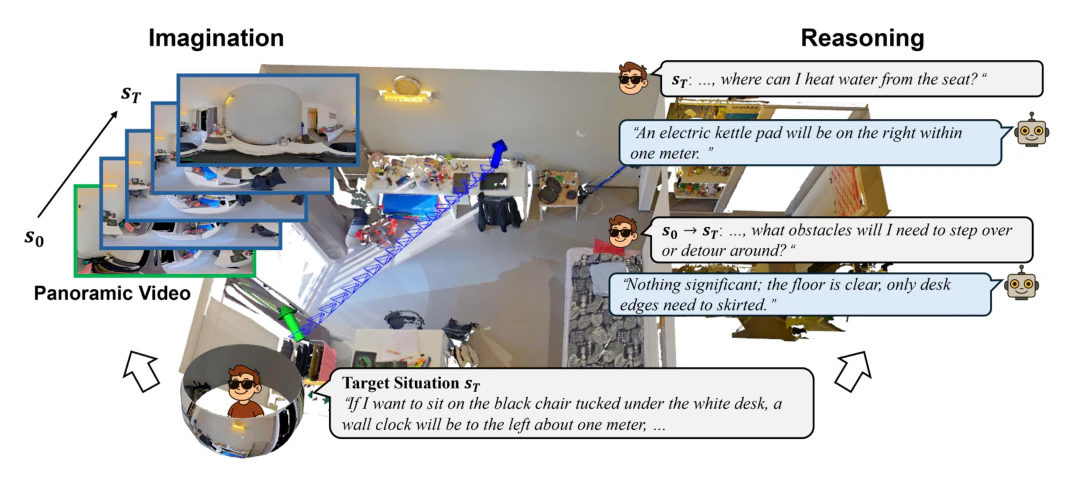
What if? Emulative Simulation with World Models for Situated Reasoning — research illustration

What if? Emulative Simulation with World Models for Situated Reasoning

R. Liu, Y. Chen, Y. Zhang, J. Zheng, K. Peng, C. Wu, C. Huang, D. Wen, J. Zhang, K. Yang, R. Stiefelhagen

ECCV 2026

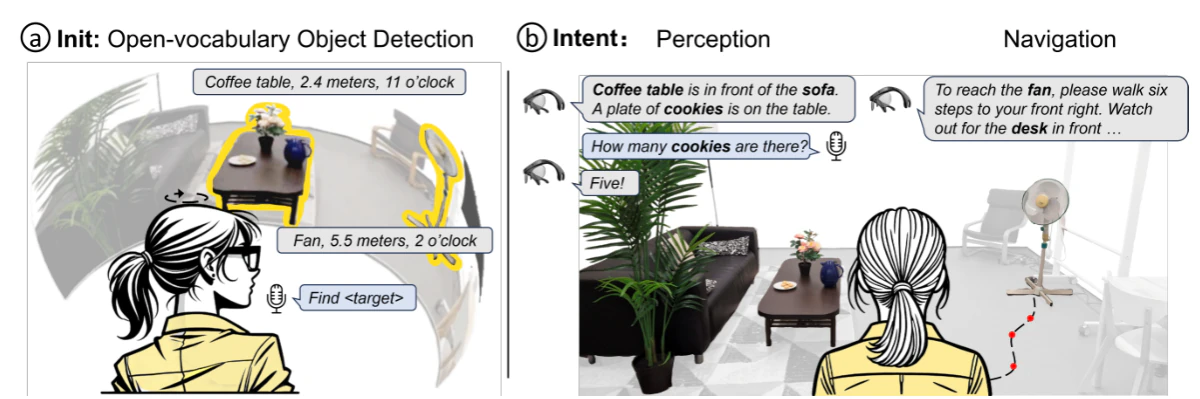
ObjectFinder: An Open-Vocabulary Assistive System for Interactive Object Search by People Who Are Blind — research illustration

ObjectFinder: An Open-Vocabulary Assistive System for Interactive Object Search by People Who Are Blind

R. Liu, J. Zhang, A. Schön, K. Müller, J. Zheng, K. Yang, A. Guo, K. Gerling, R. Stiefelhagen

International Journal of Human–Computer Interaction 2026

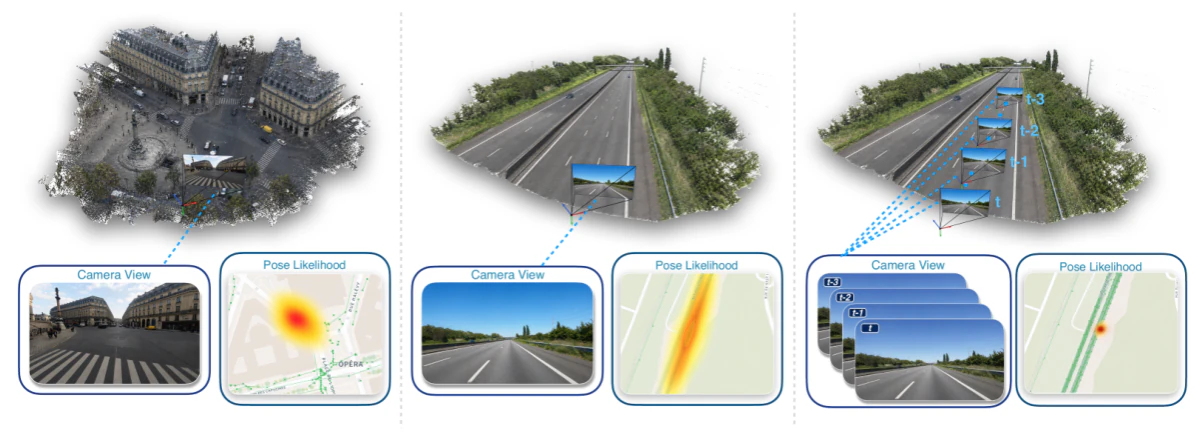
SeqLoc: Beyond the Single Frame for Cross-View Geo-Localization in Feature-Sparse Scenes — research illustration

SeqLoc: Beyond the Single Frame for Cross-View Geo-Localization in Feature-Sparse Scenes

J. Zheng, Y. Huang, R. Dai, R. Liu, Y. Chen, K. Peng, K. Yang, J. Zhang, G. Wang, O. Wysocki, R. Stiefelhagen

arXiv preprint 2026

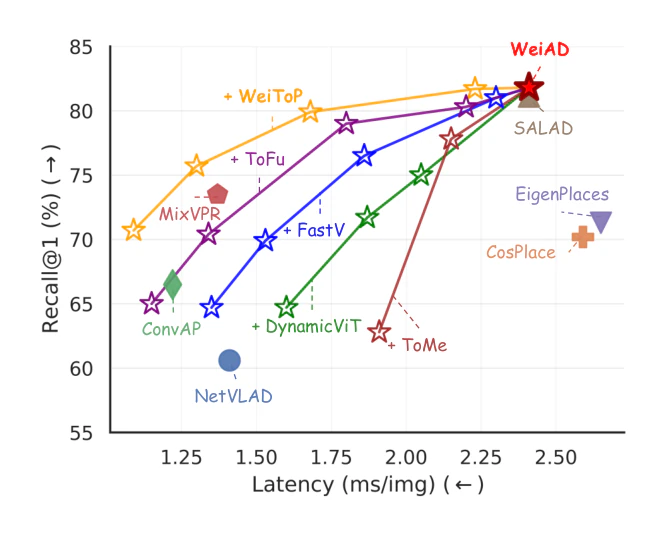
Faster or Stronger: Towards Flexible Visual Place Recognition via Weighted Aggregation and Token Pruning — research illustration

Faster or Stronger: Towards Flexible Visual Place Recognition via Weighted Aggregation and Token Pruning

Z. Zeng, J. M. Goo, J. Zheng, W. Fan, J. Zhang, R. Stiefelhagen, J. Boehm

arXiv preprint 2026

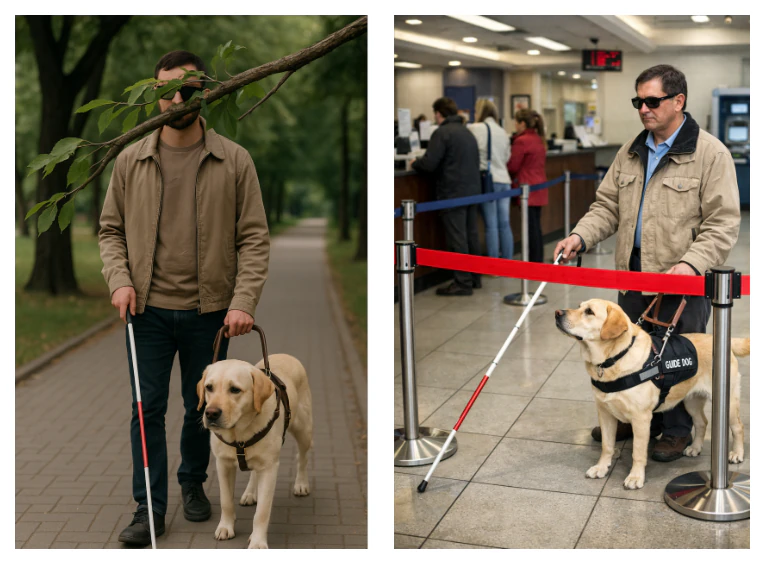
Not an Obstacle for Dog, but a Hazard for Human: A Co-Ego Navigation System for Guide Dog Robots — research illustration

Not an Obstacle for Dog, but a Hazard for Human: A Co-Ego Navigation System for Guide Dog Robots

R. Liu, Jingqi Zhang, J. Zheng, Y. Chen, P. S. Lee, D. Wen, K. Peng, J. Zhang, K. Yang, K. Mombaur, R. Stiefelhagen

arXiv preprint 2026

DriveXQA: Cross-modal Visual Question Answering for Adverse Driving Scene Understanding — research illustration

DriveXQA: Cross-modal Visual Question Answering for Adverse Driving Scene Understanding

M. Tao, R. Liu, J. Zheng, Y. Chen, K. Ying, M. S. Sarfraz, K. Yang, J. Zhang, R. Stiefelhagen

CVPR Workshops (DriveX) 2026

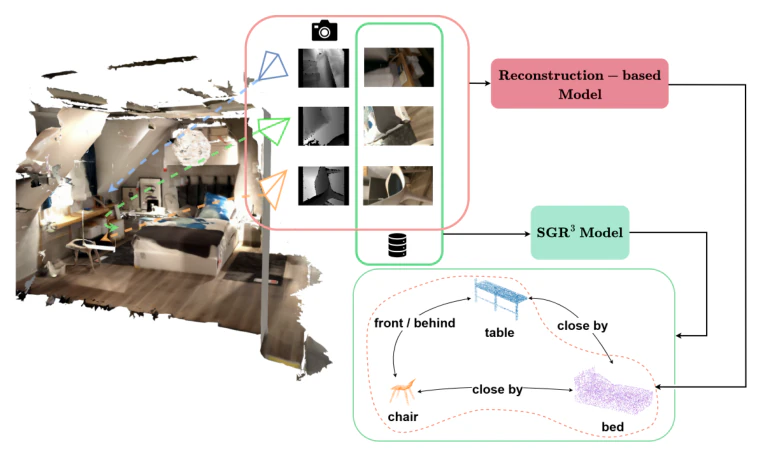
SGR3 Model: Scene Graph Retrieval-Reasoning Model in 3D — research illustration

SGR3 Model: Scene Graph Retrieval-Reasoning Model in 3D

Z. Wang, R. Liu, Y. Chen, J. Zheng, W. Fan, K. Peng, D. Wen, J. Wei, J. Zhang, R. Stiefelhagen

arXiv preprint 2026

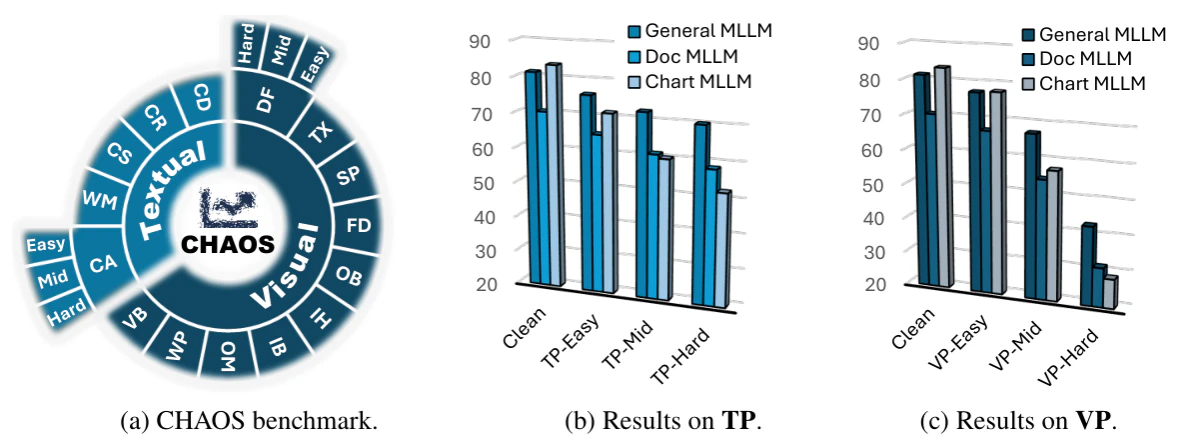
CHAOS: Chart Analysis with Outlier Samples — research illustration

CHAOS: Chart Analysis with Outlier Samples

Y. Chen, O. Moured, R. Liu, S. Reiß, P. Torr, J. Zhang, R. Stiefelhagen

IEEE ICASSP 2026

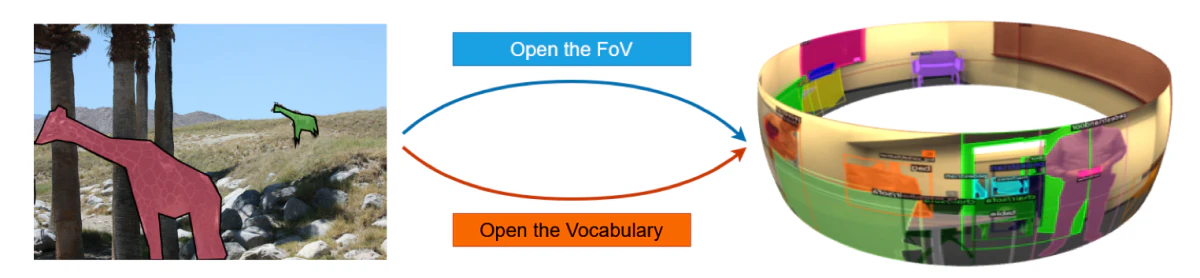
PASI: Panoramic Adaptive Sliced Inference for Open-Vocabulary Instance Segmentation in Equirectangular Panoramas — research illustration

PASI: Panoramic Adaptive Sliced Inference for Open-Vocabulary Instance Segmentation in Equirectangular Panoramas

T. Kirilov, J. Zheng, R. Liu, Y. Chen, D. Wen, J. Wei, K. Peng, K. Yang, J. Zhang, R. Stiefelhagen

ECCV Workshops (HSI) 2026

2025

mmWalk: Towards Multi-modal Multi-view Walking Assistance — research illustration

mmWalk: Towards Multi-modal Multi-view Walking Assistance

K. Ying*, R. Liu*†, C. Chen, M. Tao, H. Shi, K. Yang, J. Zhang†, R. Stiefelhagen

NeurIPS 2025

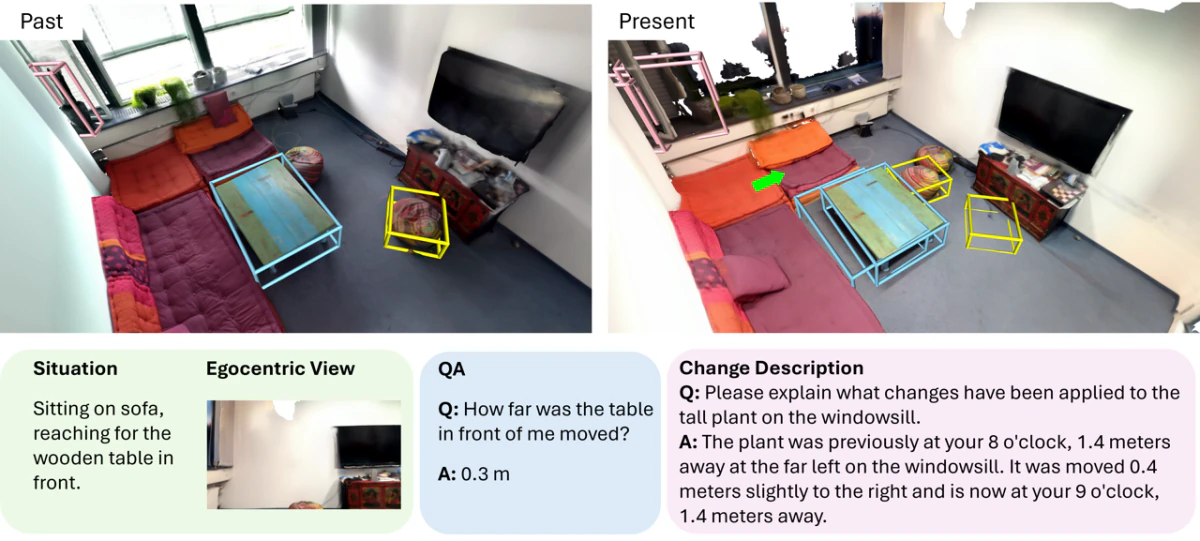
Situat3DChange: Situated 3D Change Understanding Dataset for Multimodal Large Language Model — research illustration

Situat3DChange: Situated 3D Change Understanding Dataset for Multimodal Large Language Model

R. Liu, J. Zheng, Y. Chen, Z. Wang, K. Peng, K. Yang, J. Zhang†, M. Pollefeys, R. Stiefelhagen

NeurIPS 2025

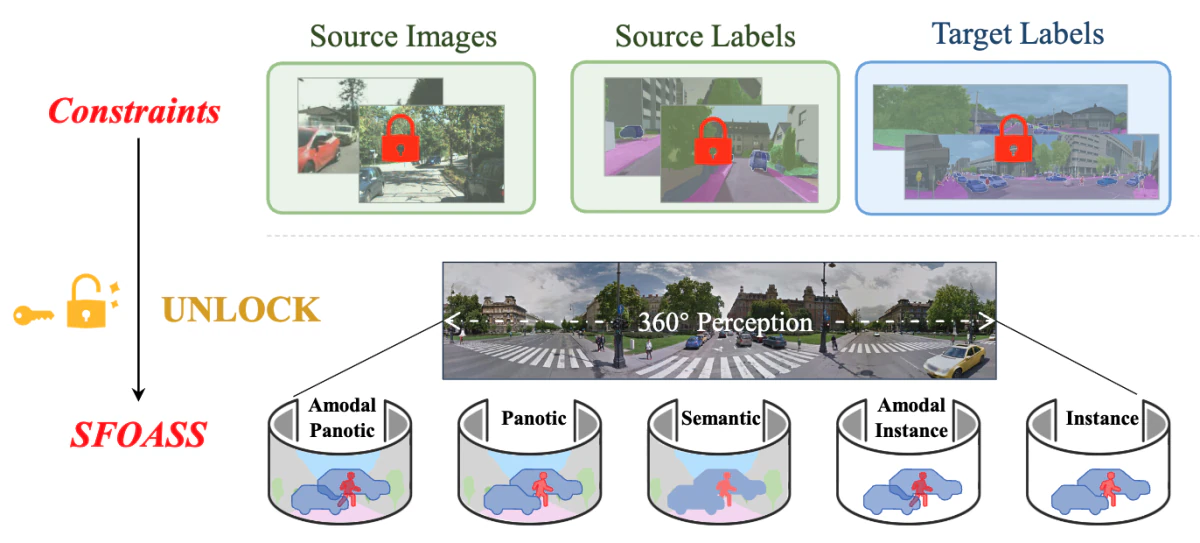
Unlocking Constraints: Source-Free Occlusion-Aware Seamless Segmentation — research illustration

Unlocking Constraints: Source-Free Occlusion-Aware Seamless Segmentation

Y. Cao*, J. Zhang*, X. Zheng, H. Shi, K. Peng, H. Liu, K. Yang, H. Zhang

ICCV 2025

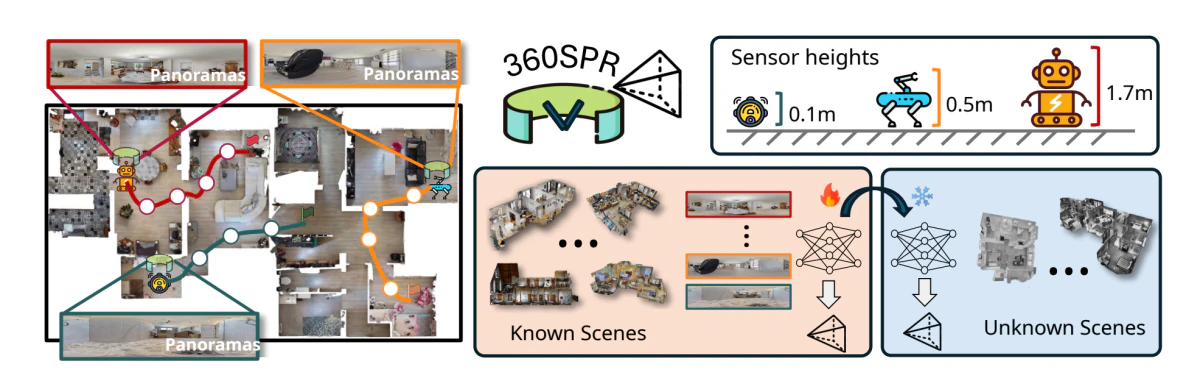
Scene-agnostic Pose Regression for Visual Localization — research illustration

Scene-agnostic Pose Regression for Visual Localization

J. Zheng, R. Liu, Y. Chen, Z. Chen, K. Yang, J. Zhang†, R. Stiefelhagen

CVPR 2025

SAMBLE: Shape-Specific Point Cloud Sampling for an Optimal Trade-Off Between Local Detail and Global Uniformity — research illustration

SAMBLE: Shape-Specific Point Cloud Sampling for an Optimal Trade-Off Between Local Detail and Global Uniformity

C. Wu, Y. Wan*, H. Fu*, J. Pfrommer, Z. Zhong, J. Zheng†, J. Zhang, J. Beyerer

CVPR 2025

Graph-based Document Structure Analysis — research illustration

Graph-based Document Structure Analysis

Y. Chen, R. Liu, J. Zheng, D. Wen, K. Peng, J. Zhang†, R. Stiefelhagen

ICLR 2025

@Bench: Benchmarking Vision-Language Models for Human-centered Assistive Technology — research illustration

@Bench: Benchmarking Vision-Language Models for Human-centered Assistive Technology

X. Jiang*, J. Zheng*, R. Liu, J. Li, J. Zhang†, S. Matthiesen, R. Stiefelhagen

WACV 2025

Solving Zero-Shot 3D Visual Grounding as Constraint Satisfaction Problems — research illustration

Solving Zero-Shot 3D Visual Grounding as Constraint Satisfaction Problems

Q. Yuan, K. Li†, J. Zhang†

BMVC 2025

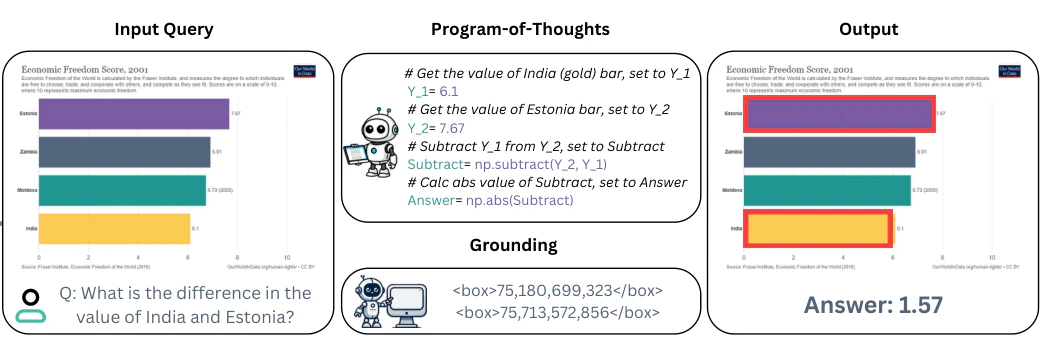
RefChartQA: Grounding Visual Answer on Chart Images Through Instruction Tuning — research illustration

RefChartQA: Grounding Visual Answer on Chart Images Through Instruction Tuning

A. Vogel, O. Moured, Y. Chen, J. Zhang, R. Stiefelhagen

ICDAR 2025

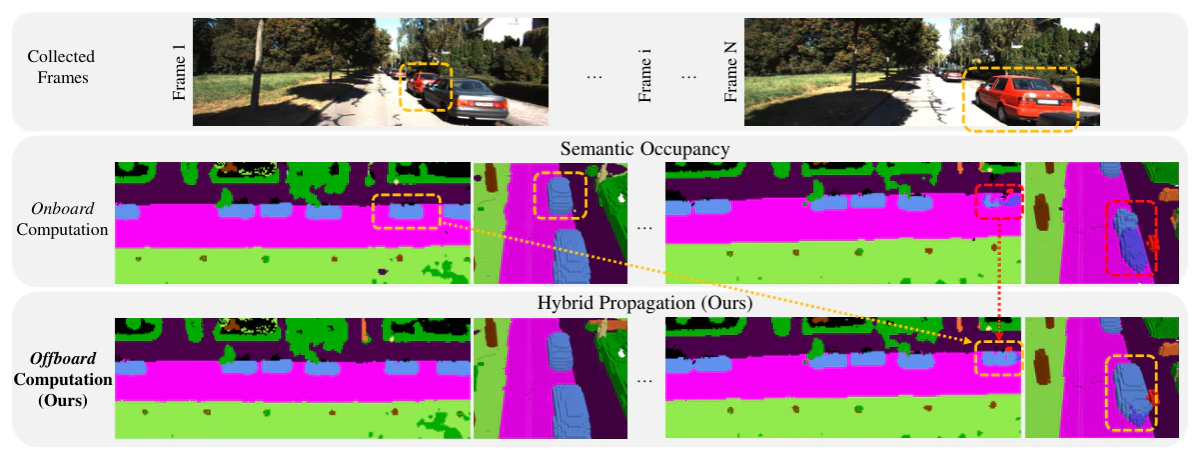
Offboard Occupancy Refinement with Hybrid Propagation for Autonomous Driving — research illustration

Offboard Occupancy Refinement with Hybrid Propagation for Autonomous Driving

H. Shi, S. Wang, J. Zhang, X. Yin, G. Wang, J. Zhu, K. Yang, K. Wang

IEEE T-ITS 2025

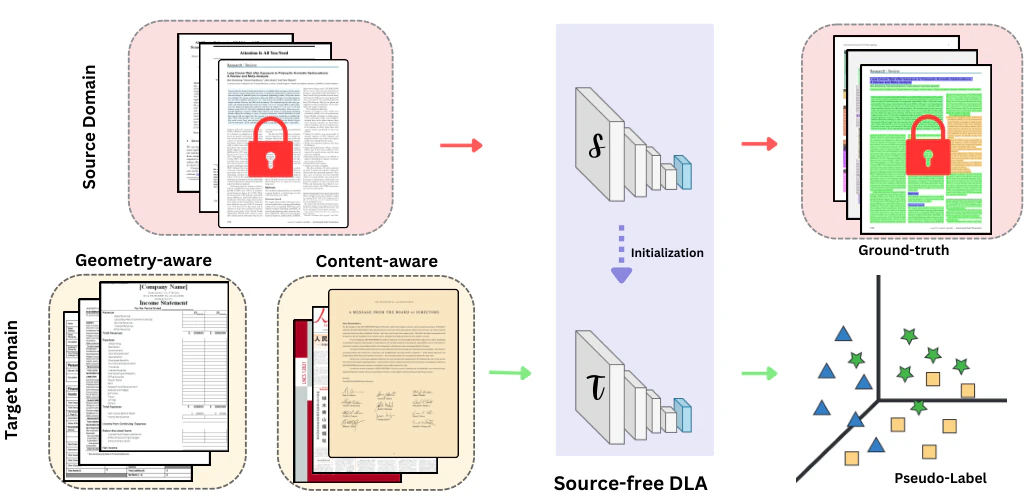
SFDLA: Source-Free Document Layout Analysis — research illustration

SFDLA: Source-Free Document Layout Analysis

S. Tewes*, Y. Chen*, O. Moured, J. Zhang†, R. Stiefelhagen

ICDAR 2025

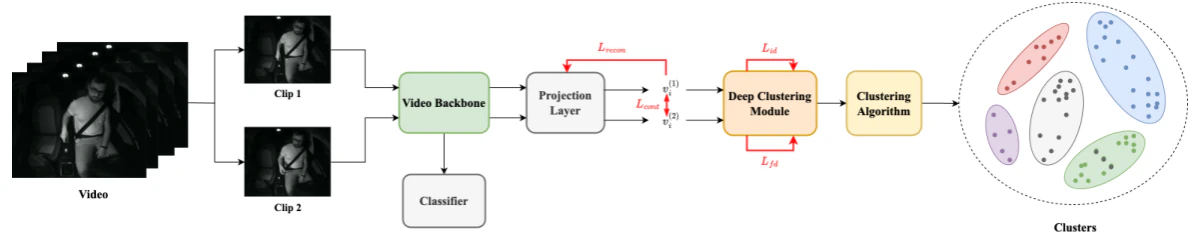
Exploring Video-Based Driver Activity Recognition under Noisy Labels — research illustration

Exploring Video-Based Driver Activity Recognition under Noisy Labels

L. Fan, D. Wen, K. Peng, K. Yang, J. Zhang, R. Liu, Y. Chen, J. Zheng, J. Wu, X. Han, R. Stiefelhagen

IEEE SMC 2025

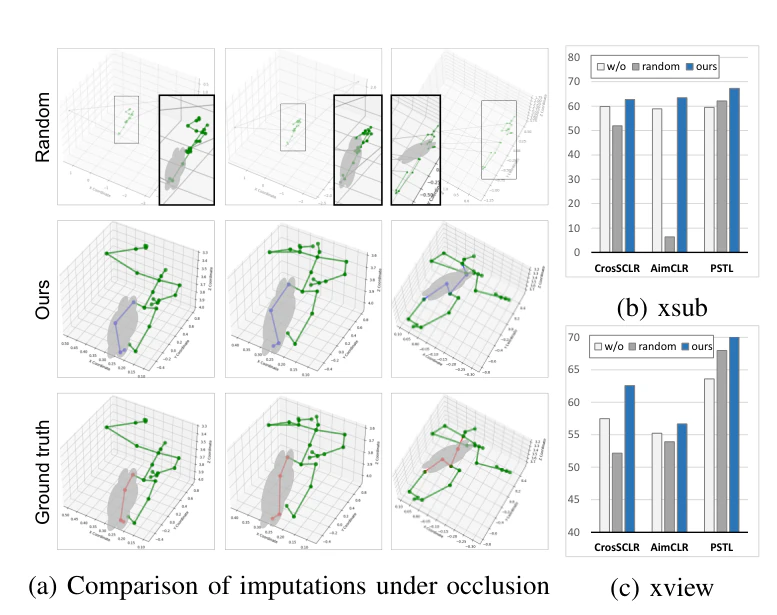
Exploring Self-supervised Skeleton-based Action Recognition in Occluded Environments — research illustration

Exploring Self-supervised Skeleton-based Action Recognition in Occluded Environments

Y. Chen, K. Peng, A. Roitberg, D. Schneider, J. Zhang, J. Zheng, Y. Chen, R. Liu, K. Yang, R. Stiefelhagen

IEEE IJCNN 2025

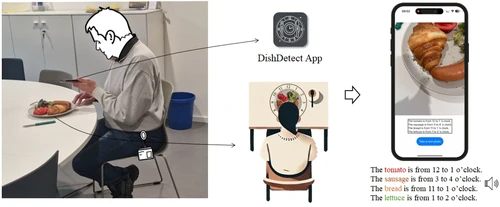
DishDetect: What’s on My Plate? – Co-Designing a Mobile App for Clockwise Food Description — research illustration

DishDetect: What’s on My Plate? – Co-Designing a Mobile App for Clockwise Food Description

K. Ying*, M. Tao*, R. Dai*, R. Liu, K. Müller, G. Jaworek, J. Zhang, R. Stiefelhagen

CHI Extended Abstracts 2025

2024
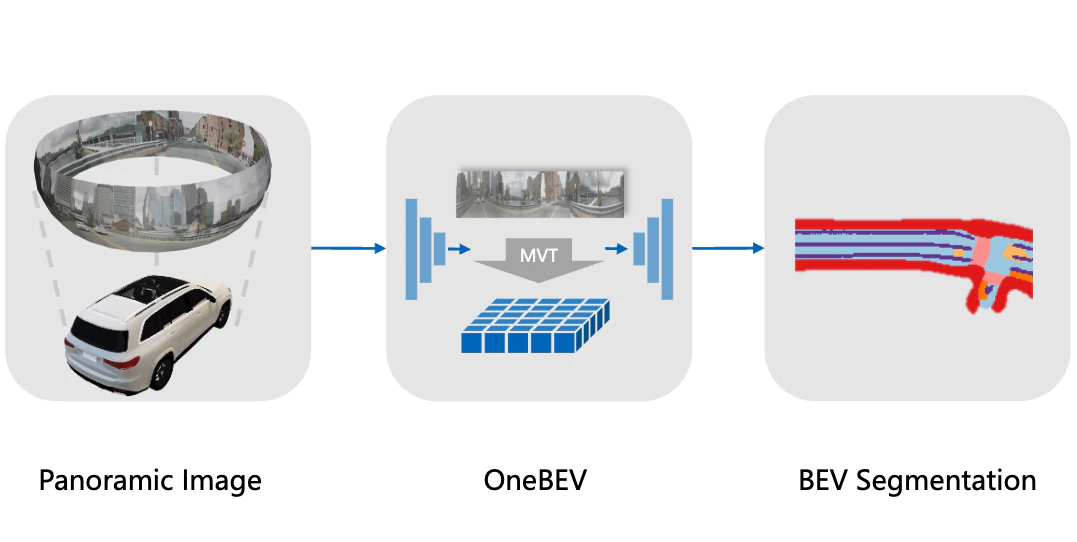
OneBEV: Using One Panoramic Image for Bird's-Eye-View Semantic Mapping — research illustration

OneBEV: Using One Panoramic Image for Bird's-Eye-View Semantic Mapping

J. Wei, J. Zheng, R. Liu, J. Hu, J. Zhang†, R. Stiefelhagen

ACCV 2024 (🏆 Best Paper Finalist)

Behind Every Domain There is a Shift: Adapting Distortion-aware Vision Transformers for Panoramic Semantic Segmentation — research illustration

Behind Every Domain There is a Shift: Adapting Distortion-aware Vision Transformers for Panoramic Semantic Segmentation

J. Zhang, K. Yang, H. Shi, S. Reiß, K. Peng, C. Ma, H. Fu, P. Torr, K. Wang, R. Stiefelhagen

IEEE T-PAMI 2024

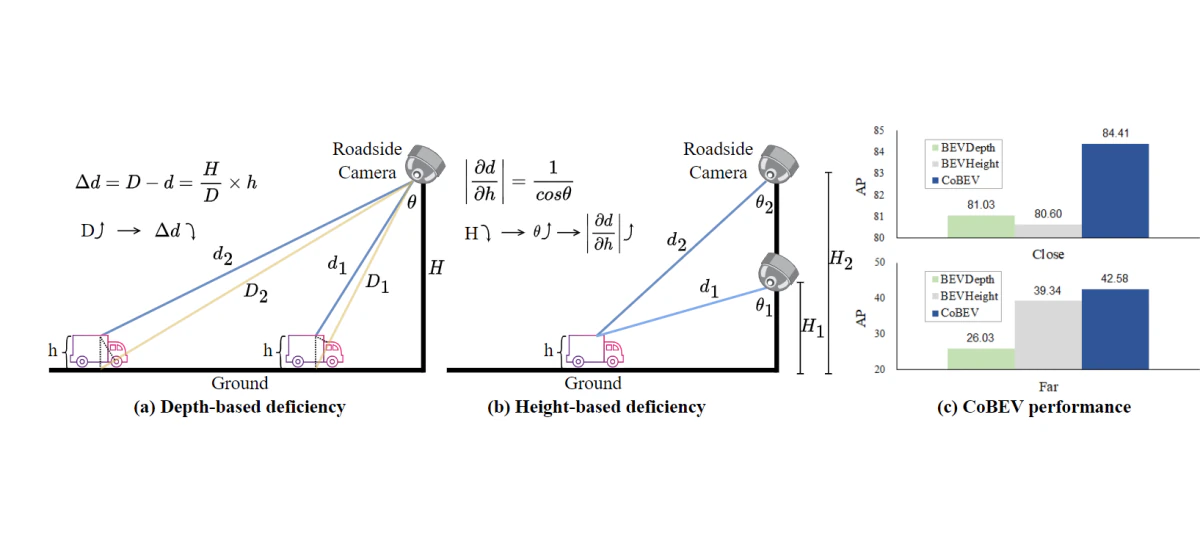
CoBEV: Elevating Roadside 3D Object Detection with Depth and Height Complementarity — research illustration

CoBEV: Elevating Roadside 3D Object Detection with Depth and Height Complementarity

H. Shi*, C. Peng*, J. Zhang*, K. Yang, Y. Wu, H. Ni, Y. Lin, R. Stiefelhagen, K. Wang

IEEE T-IP 2024

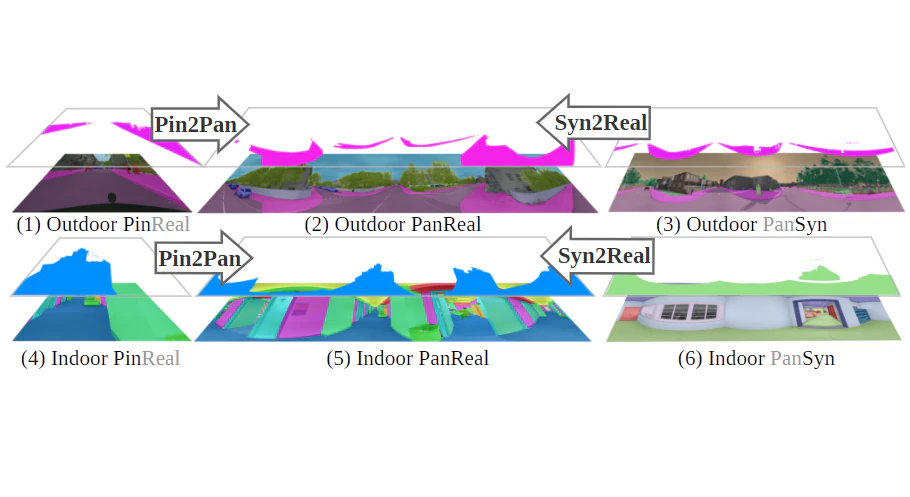
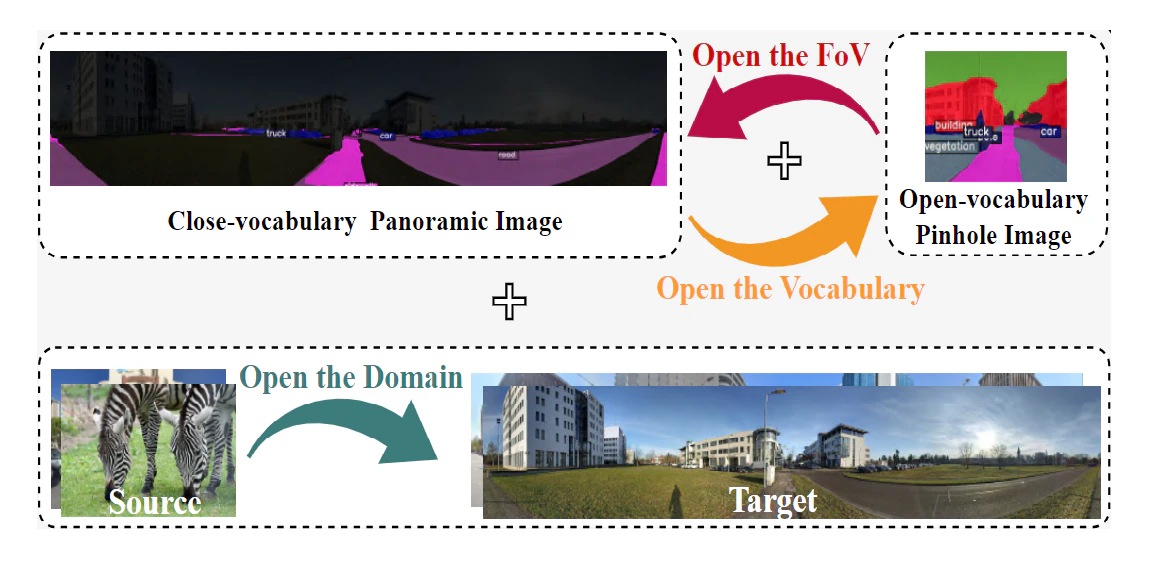
Open Panoramic Segmentation — research illustration

Open Panoramic Segmentation

J. Zheng, R. Liu, Y. Chen, K. Peng, C. Wu, K. Yang, J. Zhang†, R. Stiefelhagen

ECCV 2024

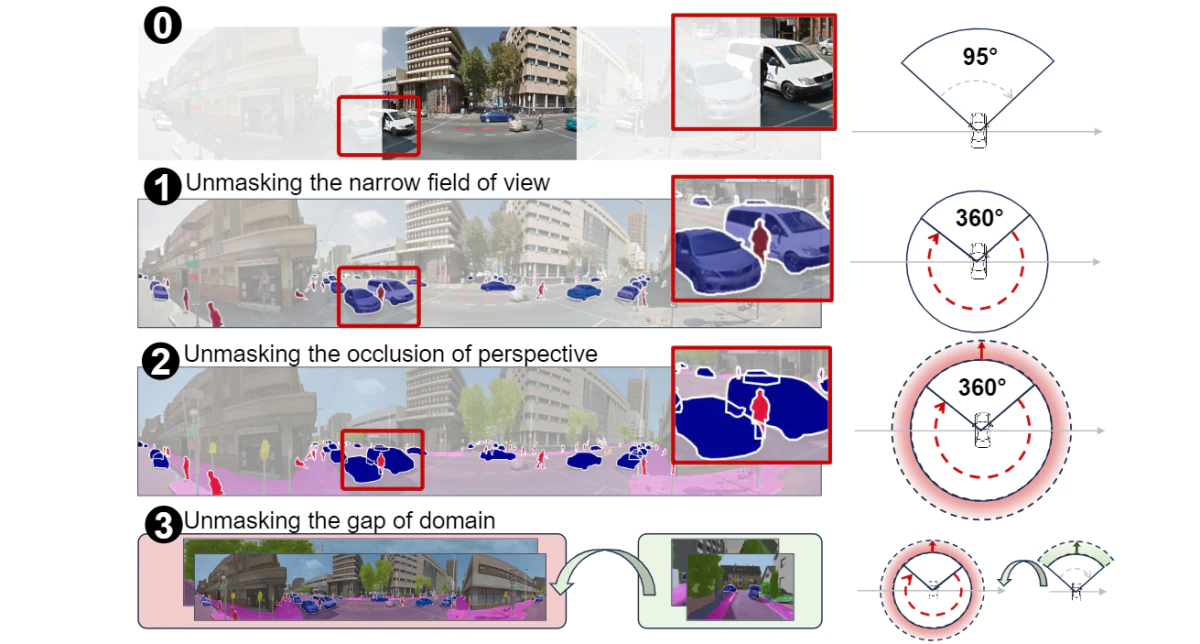
Occlusion-Aware Seamless Segmentation — research illustration

Occlusion-Aware Seamless Segmentation

Y. Cao*, J. Zhang*, H. Shi, K. Peng, Y. Zhang, H. Zhang, R. Stiefelhagen, K. Yang

ECCV 2024

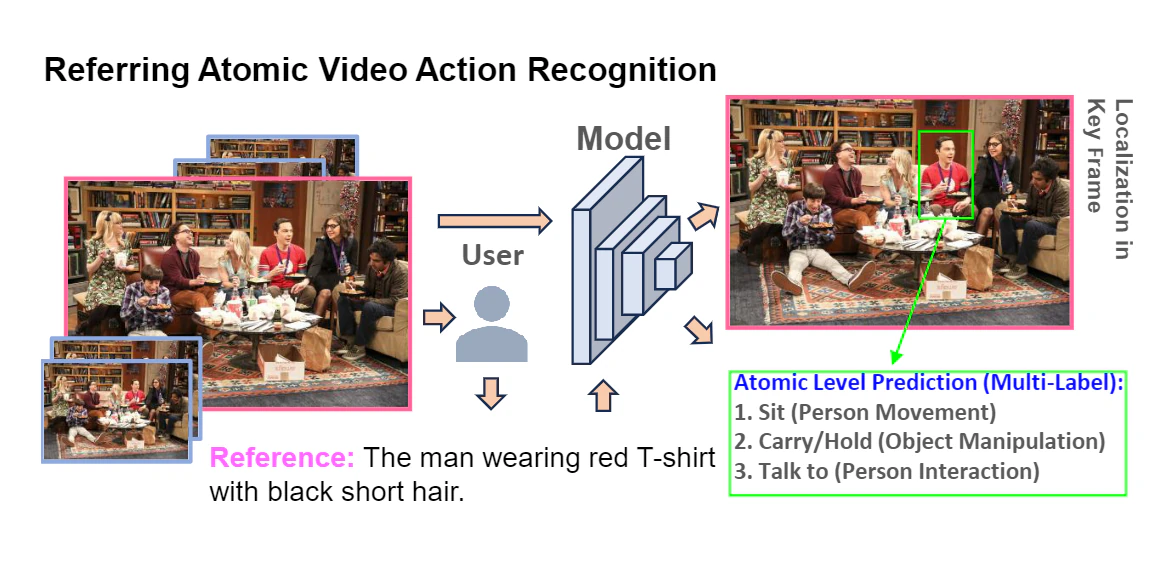
Referring Atomic Video Action Recognition — research illustration

Referring Atomic Video Action Recognition

K. Peng, J. Fu, K. Yang, D. Wen, Y. Chen, R. Liu, J. Zheng, J. Zhang, M. S. Sarfraz, R. Stiefelhagen, A. Roitberg

ECCV 2024

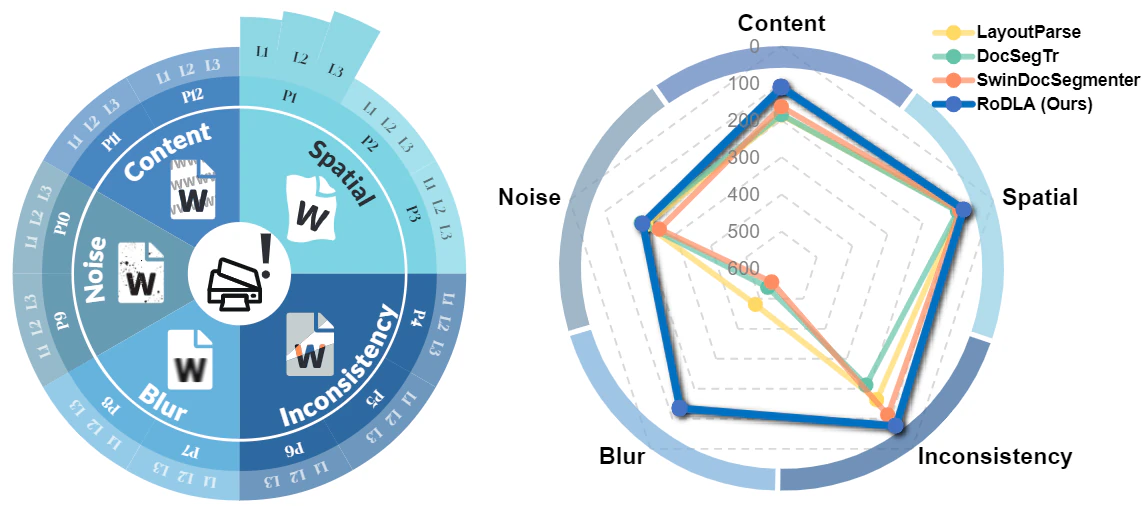
RoDLA: Benchmarking the Robustness of Document Layout Analysis Models — research illustration

RoDLA: Benchmarking the Robustness of Document Layout Analysis Models

Y. Chen, J. Zhang†, K. Peng, J. Zheng, R. Liu, P. Torr, R. Stiefelhagen

CVPR 2024

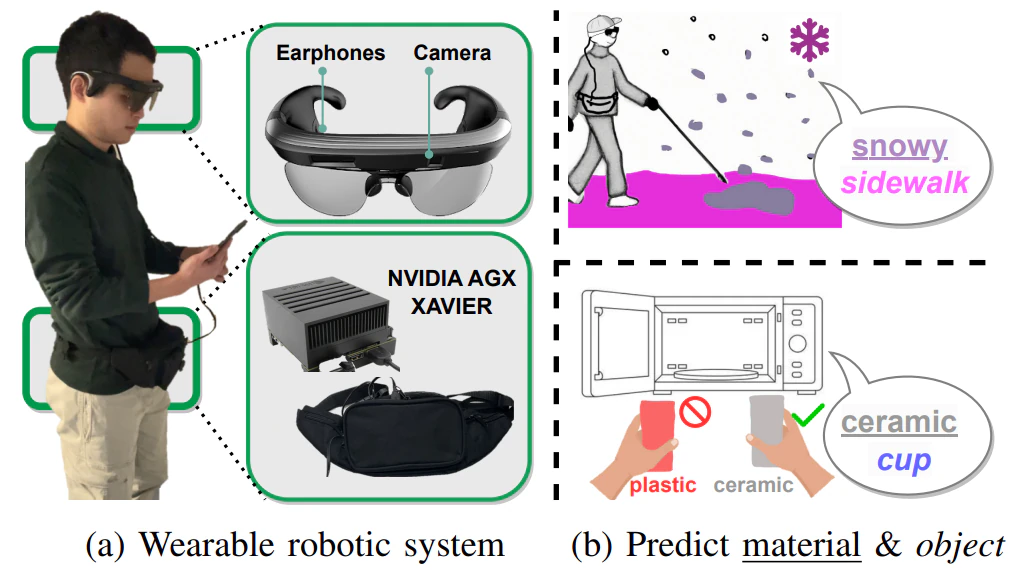
MateRobot: Material Recognition in Wearable Robotics for People with Visual Impairments — research illustration

MateRobot: Material Recognition in Wearable Robotics for People with Visual Impairments

J. Zheng*, J. Zhang*, K. Yang, K. Peng, R. Stiefelhagen

IEEE ICRA 2024 (🏆 Best Paper Finalist on HRI)
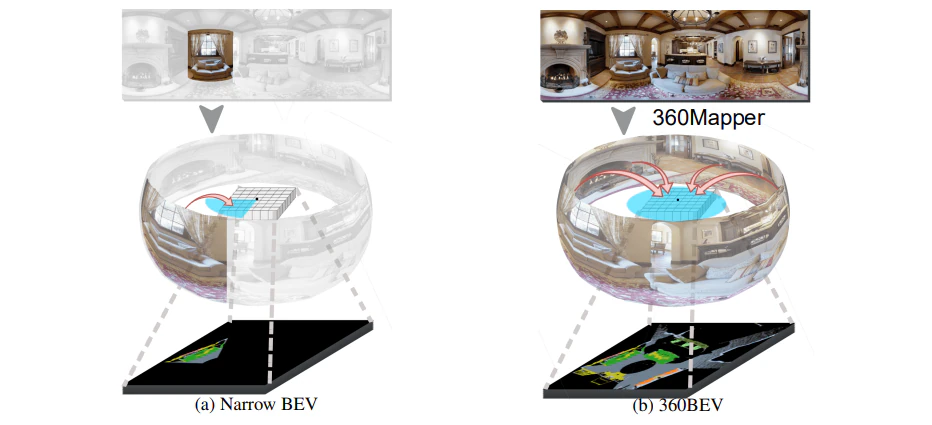
360BEV: Panoramic Semantic Mapping for Indoor Bird's-Eye View — research illustration

360BEV: Panoramic Semantic Mapping for Indoor Bird's-Eye View

Z. Teng*, J. Zhang*†, K. Yang, K. Peng, H. Shi, S. Reiß, K. Cao, R. Stiefelhagen

WACV 2024

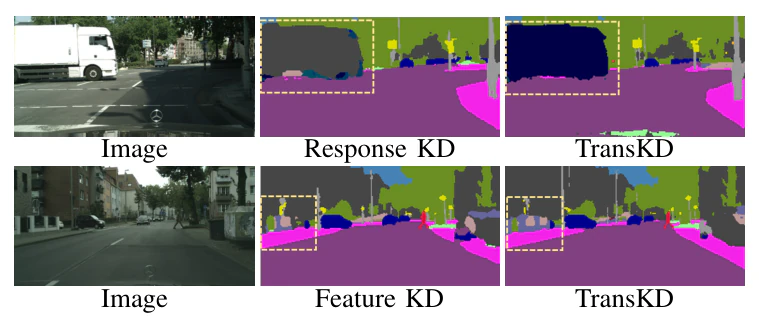
TransKD: Transformer Knowledge Distillation for Efficient Semantic Segmentation — research illustration

TransKD: Transformer Knowledge Distillation for Efficient Semantic Segmentation

R. Liu, K. Yang, A. Roitberg, J. Zhang, K. Peng, H. Liu, Y. Wang, R. Stiefelhagen

IEEE T-ITS 2024

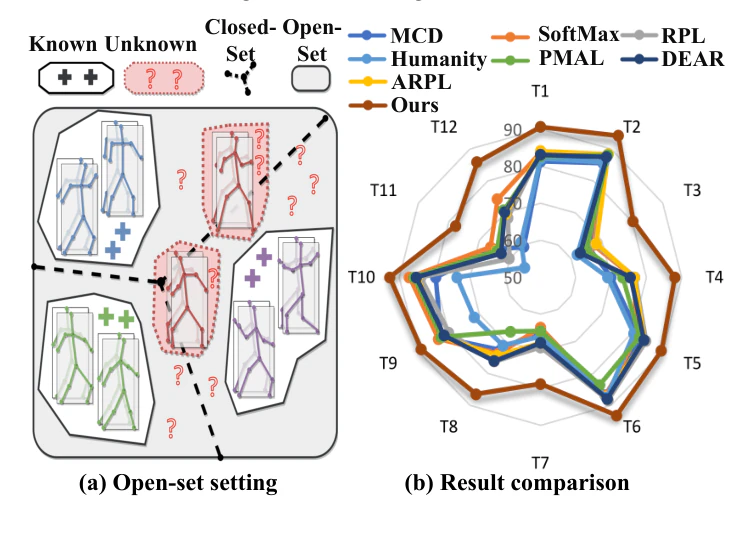
Navigating Open Set Scenarios for Skeleton-Based Action Recognition — research illustration

Navigating Open Set Scenarios for Skeleton-Based Action Recognition

K. Peng, C. Yin, J. Zheng, R. Liu, D. Schneider, J. Zhang, K. Yang, M. S. Sarfraz, R. Stiefelhagen, A. Roitberg

AAAI 2024

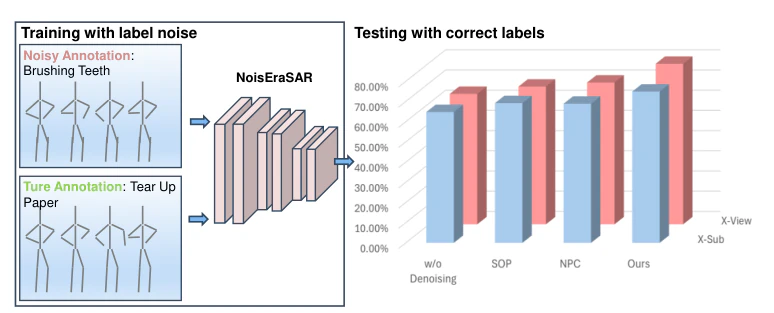
Skeleton-Based Human Action Recognition with Noisy Labels — research illustration

Skeleton-Based Human Action Recognition with Noisy Labels

Y. Xu, K. Peng, D. Wen, R. Liu, J. Zheng, Y. Chen, J. Zhang, A. Roitberg, K. Yang, R. Stiefelhagen

IEEE/RSJ IROS 2024

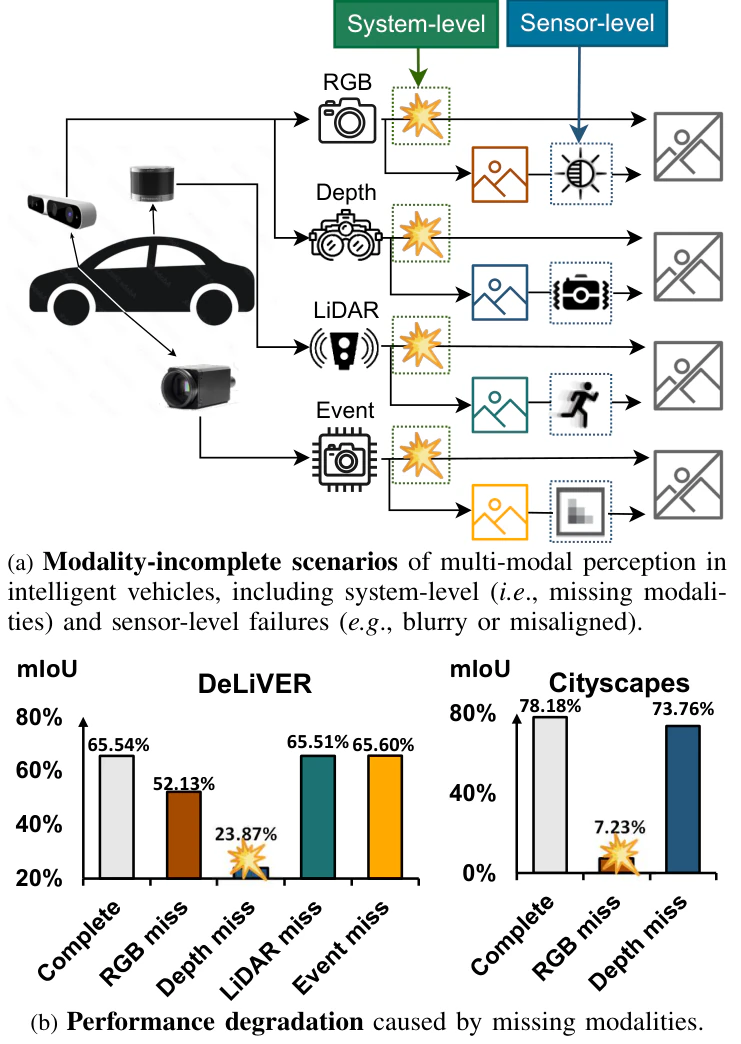
Fourier Prompt Tuning for Modality-Incomplete Scene Segmentation — research illustration

Fourier Prompt Tuning for Modality-Incomplete Scene Segmentation

R. Liu, J. Zhang, K. Peng, Y. Chen, K. Cao, J. Zheng, M. S. Sarfraz, K. Yang, R. Stiefelhagen

IEEE IV 2024

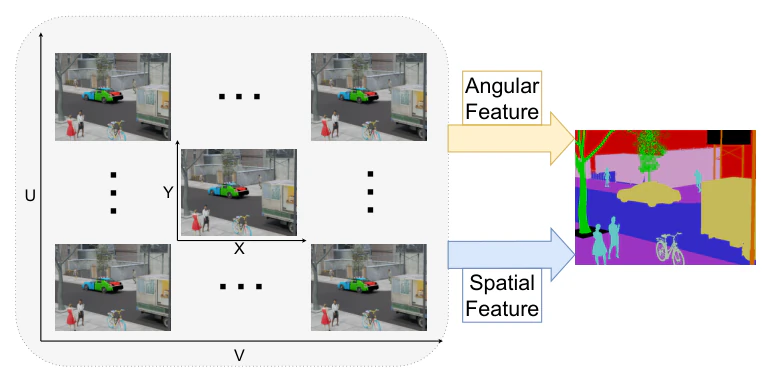
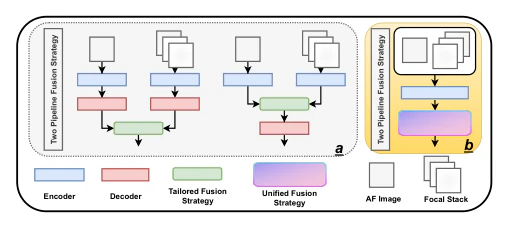
OAFuser: Towards Omni-Aperture Fusion for Light Field Semantic Segmentation — research illustration

OAFuser: Towards Omni-Aperture Fusion for Light Field Semantic Segmentation

F. Teng, J. Zhang, K. Peng, Y. Wang, R. Stiefelhagen, K. Yang

IEEE T-AI 2024

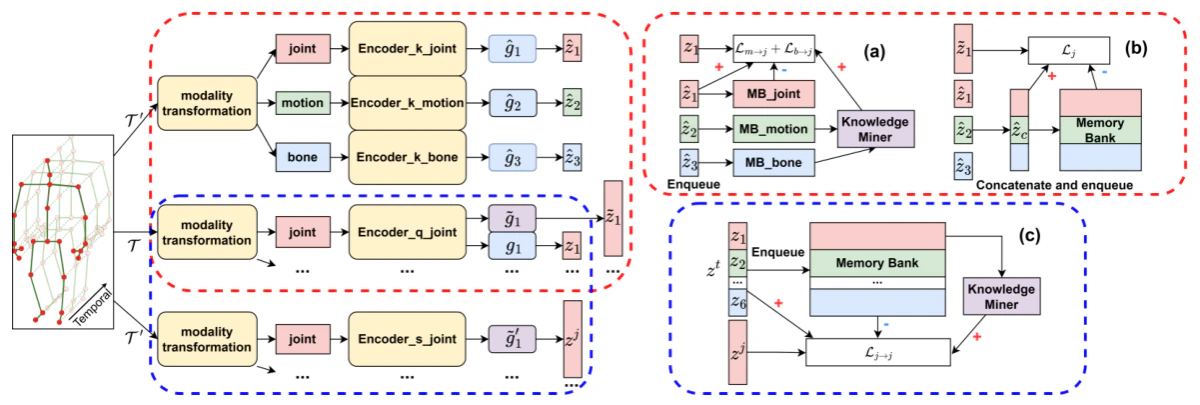
Elevating Skeleton-Based Action Recognition with Efficient Multi-Modality Self-Supervision — research illustration

Elevating Skeleton-Based Action Recognition with Efficient Multi-Modality Self-Supervision

Y. Wei, K. Peng, A. Roitberg, J. Zhang, J. Zheng, R. Liu, Y. Chen, K. Yang, R. Stiefelhagen

IEEE ICASSP 2024

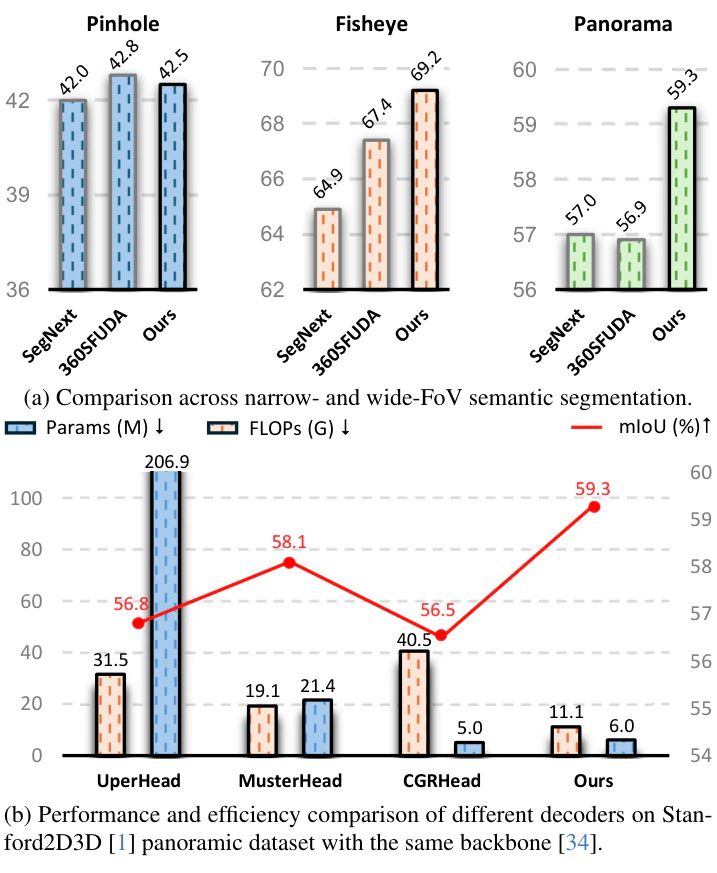
Deformable Mamba for Wide Field of View Segmentation — research illustration

Deformable Mamba for Wide Field of View Segmentation

J. Hu, J. Zheng, J. Wei, J. Zhang†, R. Stiefelhagen

arXiv preprint 2024

LF Tracy: A Unified Single-Pipeline Paradigm for Salient Object Detection in Light Field Cameras — research illustration

LF Tracy: A Unified Single-Pipeline Paradigm for Salient Object Detection in Light Field Cameras

F. Teng, J. Zhang, J. Liu, K. Peng, X. Cheng, Z. Li, K. Yang

ICPR 2024

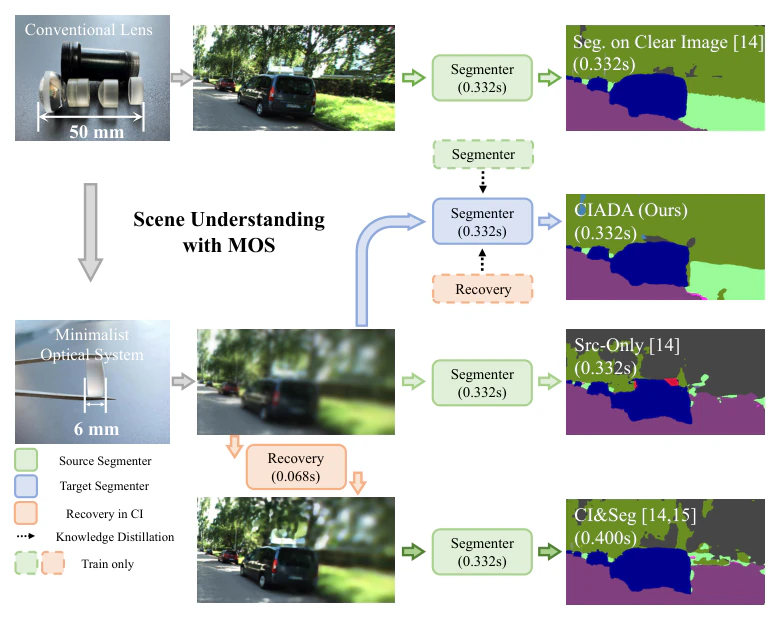
Computational Imaging for Machine Perception: Transferring Semantic Segmentation Beyond Aberrations — research illustration

Computational Imaging for Machine Perception: Transferring Semantic Segmentation Beyond Aberrations

Q. Jiang, H. Shi, S. Gao, J. Zhang, K. Yang, L. Sun, H. Ni, K. Wang

IEEE T-CI 2024

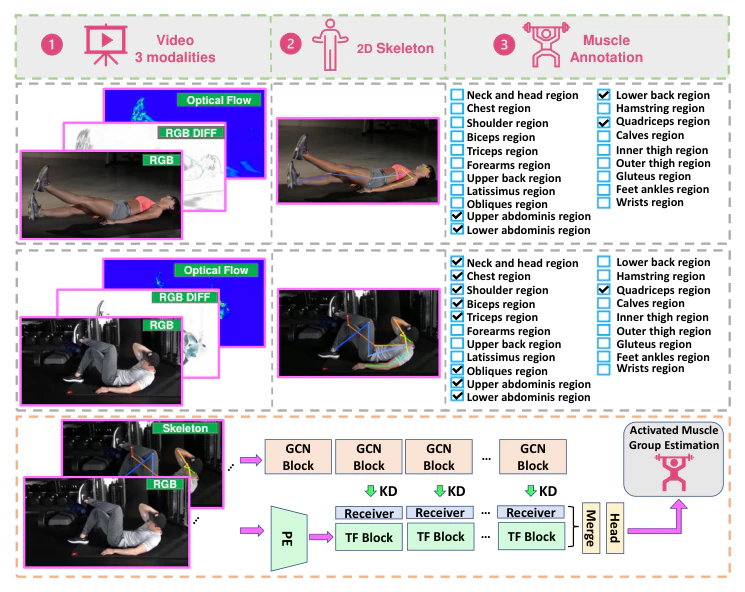
Towards Video-based Activated Muscle Group Estimation in the Wild — research illustration

Towards Video-based Activated Muscle Group Estimation in the Wild

K. Peng, D. Schneider, A. Roitberg, K. Yang, J. Zhang, C. Deng, K. Zhang, M. S. Sarfraz, R. Stiefelhagen

ACM MM 2024

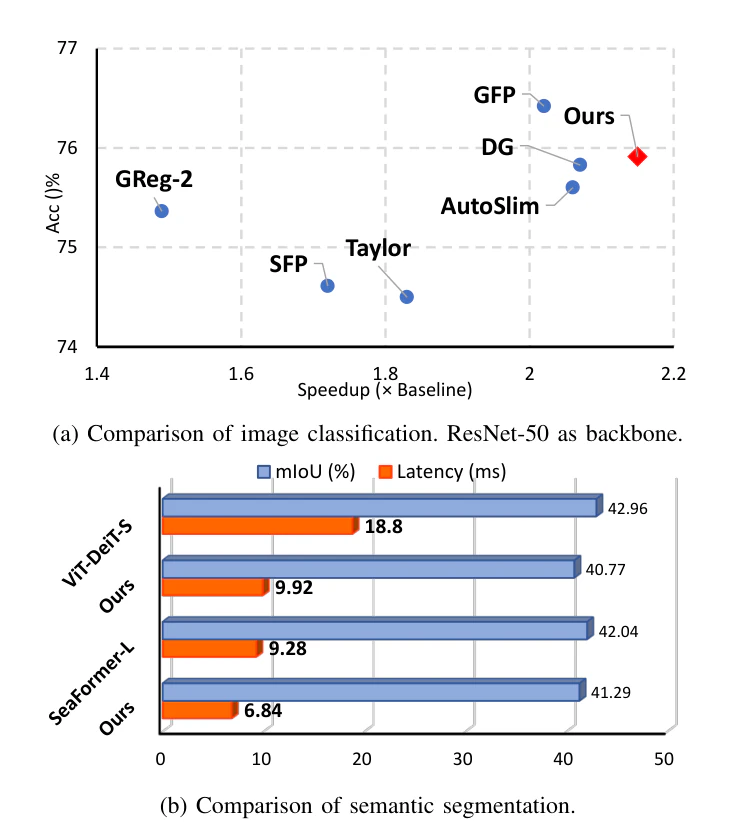
Comb, Prune, Distill: Towards Unified Pruning for Vision Model Compression — research illustration

Comb, Prune, Distill: Towards Unified Pruning for Vision Model Compression

J. Schmitt, R. Liu, J. Zheng, J. Zhang, R. Stiefelhagen

IEEE ITSC 2024

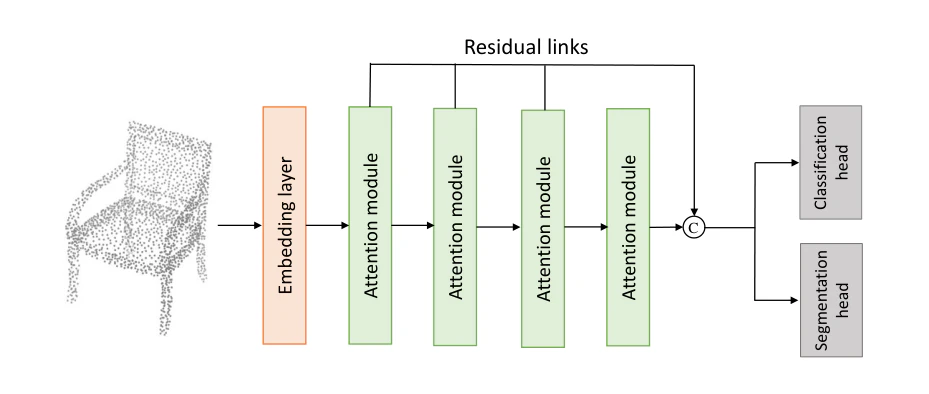
Rethinking Attention Module Design for Point Cloud Analysis — research illustration

Rethinking Attention Module Design for Point Cloud Analysis

C. Wu, K. Wang, Z. Zhong, H. Fu, J. Zheng, J. Zhang, J. Pfrommer, J. Beyerer

ICPR 2024

2023

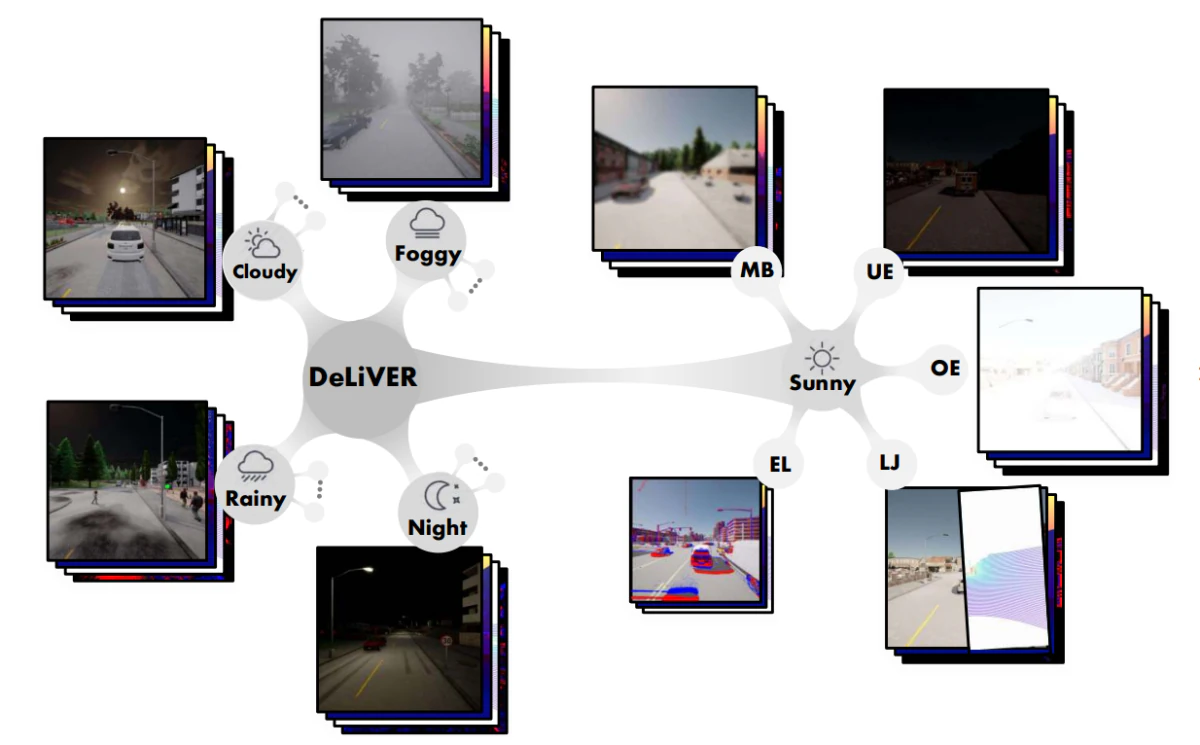
Delivering Arbitrary-Modal Semantic Segmentation — research illustration

Delivering Arbitrary-Modal Semantic Segmentation

J. Zhang*, R. Liu*, H. Shi, K. Yang, S. Reiß, K. Peng, H. Fu, K. Wang, R. Stiefelhagen

CVPR 2023

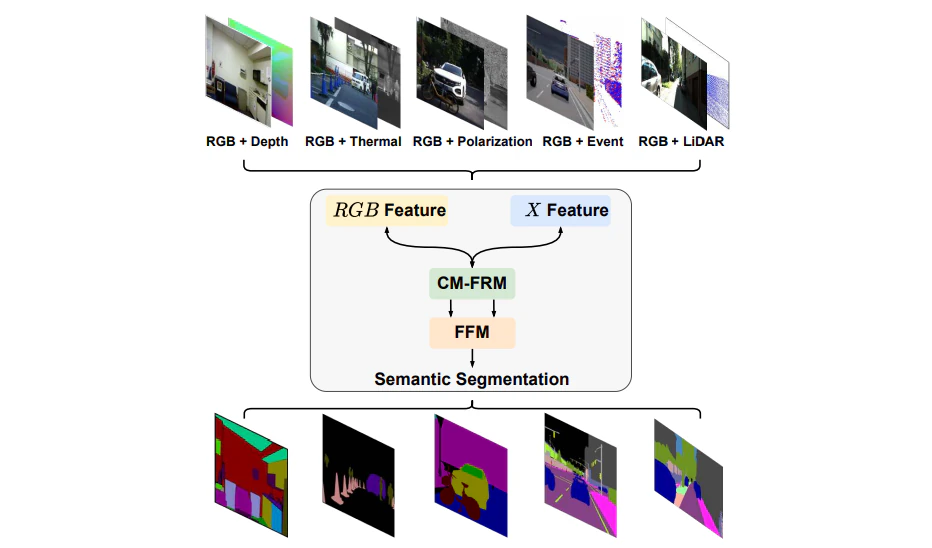
CMX: Cross-Modal Fusion for RGB-X Semantic Segmentation With Transformers — research illustration

CMX: Cross-Modal Fusion for RGB-X Semantic Segmentation With Transformers

J. Zhang*, H. Liu*, K. Yang*, X. Hu, R. Liu, R. Stiefelhagen

IEEE T-ITS 2023

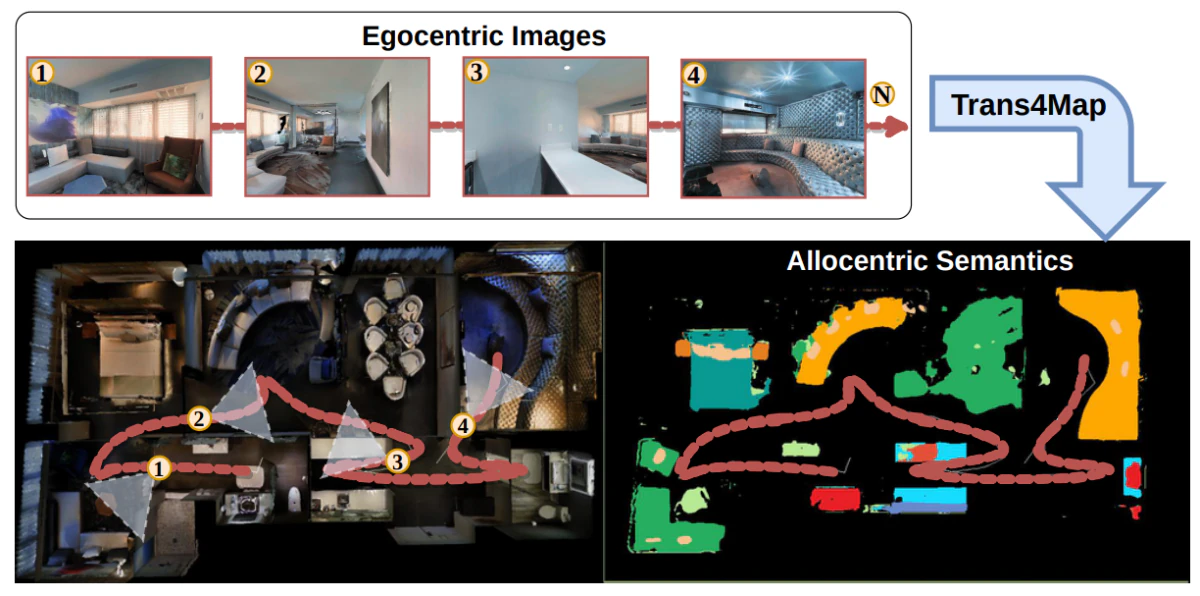
Trans4Map: Revisiting Holistic Bird's-Eye-View Mapping from Egocentric Images to Allocentric Semantics with Vision Transformers — research illustration

Trans4Map: Revisiting Holistic Bird's-Eye-View Mapping from Egocentric Images to Allocentric Semantics with Vision Transformers

C. Chen, J. Zhang†, K. Yang, K. Peng, R. Stiefelhagen

WACV 2023

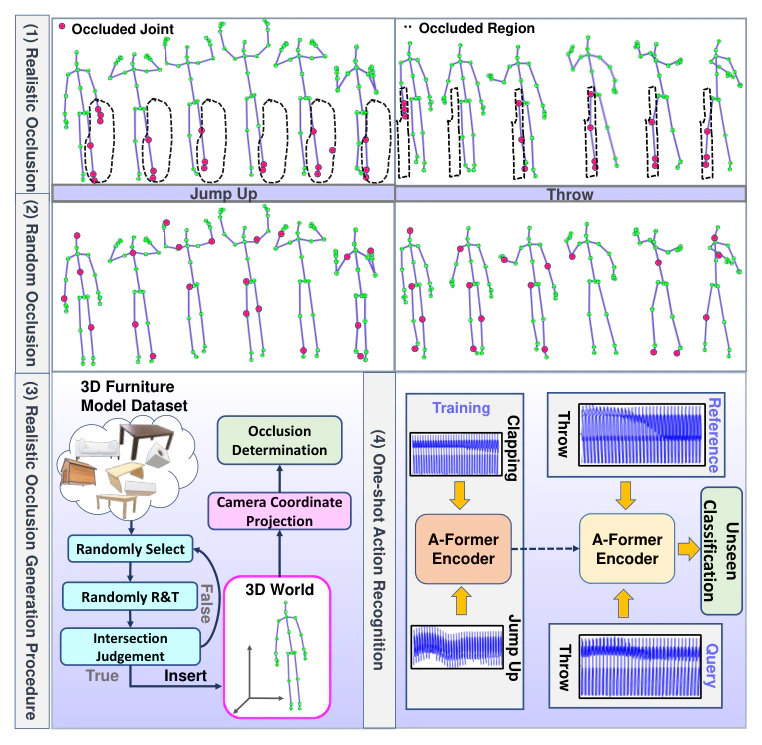
Delving Deep into One-Shot Skeleton-Based Action Recognition with Diverse Occlusions — research illustration

Delving Deep into One-Shot Skeleton-Based Action Recognition with Diverse Occlusions

K. Peng, A. Roitberg, K. Yang, J. Zhang, R. Stiefelhagen

IEEE T-MM 2023

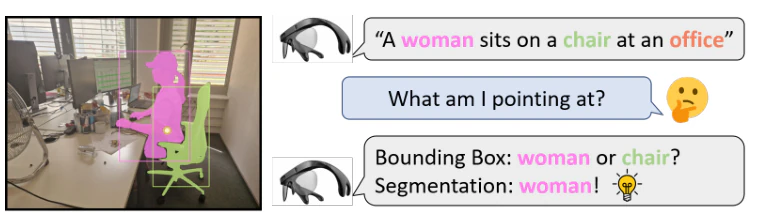
Open Scene Understanding: Grounded Situation Recognition Meets Segment Anything for Helping People with Visual Impairments — research illustration

Open Scene Understanding: Grounded Situation Recognition Meets Segment Anything for Helping People with Visual Impairments

R. Liu, J. Zhang, K. Peng, J. Zheng, K. Cao, Y. Chen, K. Yang, R. Stiefelhagen

ICCV Workshops 2023

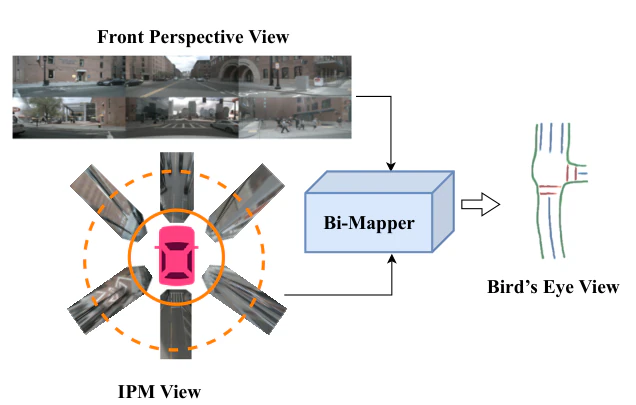
Bi-Mapper: Holistic BEV Semantic Mapping for Autonomous Driving — research illustration

Bi-Mapper: Holistic BEV Semantic Mapping for Autonomous Driving

S. Li, K. Yang, H. Shi, J. Zhang, J. Lin, Z. Teng, Z. Li

IEEE RA-L 2023

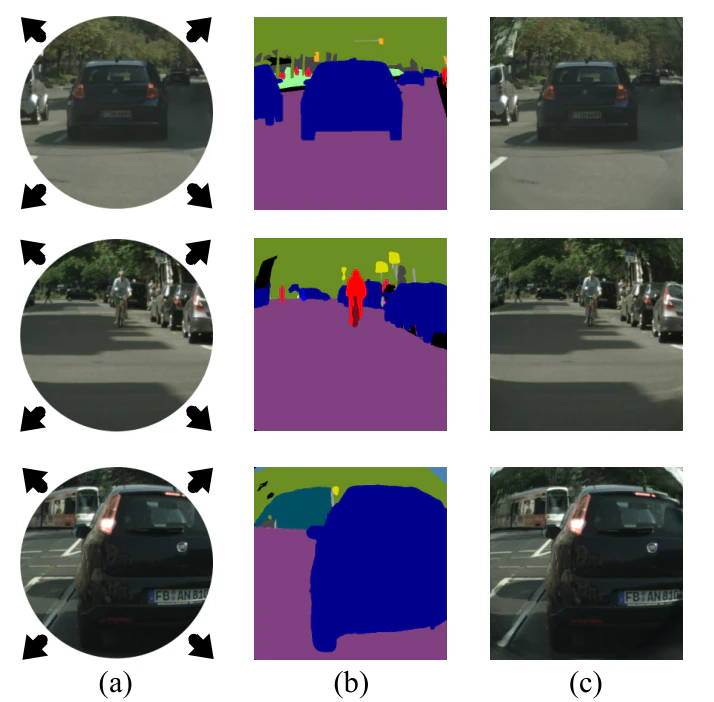
FishDreamer: Towards Fisheye Semantic Completion via Unified Image Outpainting and Segmentation — research illustration

FishDreamer: Towards Fisheye Semantic Completion via Unified Image Outpainting and Segmentation

H. Shi, Y. Li, K. Yang, J. Zhang, K. Peng, A. Roitberg, Y. Ye, H. Ni, K. Wang, R. Stiefelhagen

CVPR Workshops (OmniCV) 2023

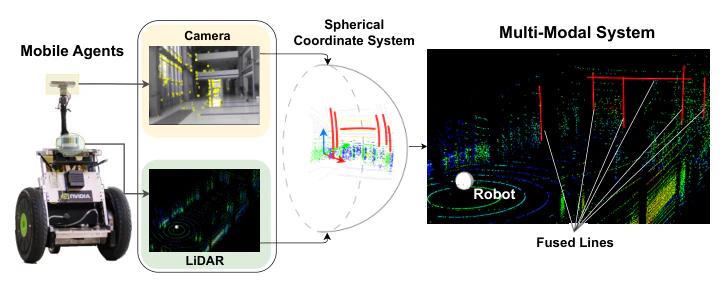
Tightly-Coupled LiDAR-Visual SLAM Based on Geometric Features for Mobile Agents — research illustration

Tightly-Coupled LiDAR-Visual SLAM Based on Geometric Features for Mobile Agents

K. Cao, R. Liu, Z. Wang, K. Peng, J. Zhang, J. Zheng, Z. Teng, K. Yang, R. Stiefelhagen

IEEE ROBIO 2023

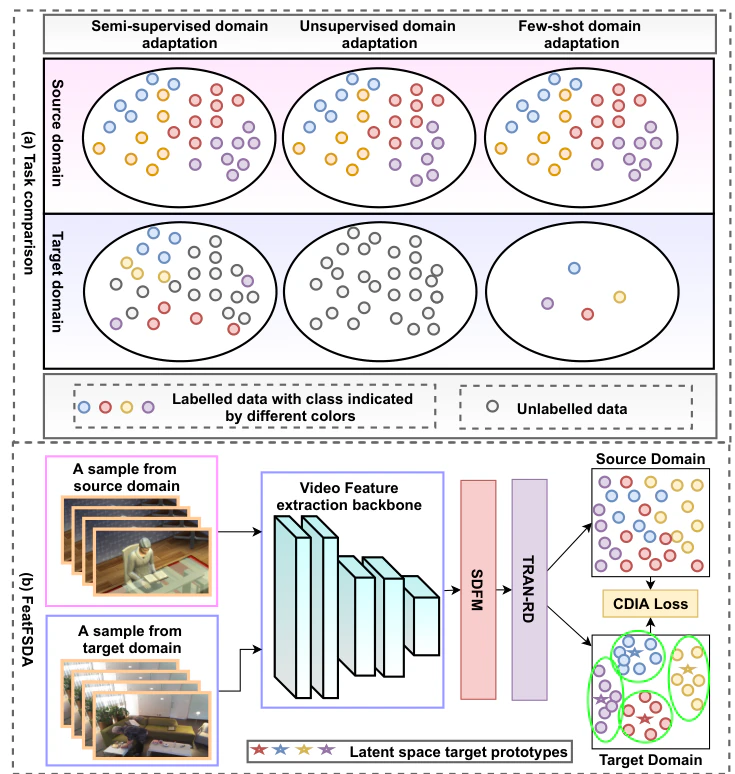
Exploring Few-Shot Adaptation for Activity Recognition on Diverse Domains — research illustration

Exploring Few-Shot Adaptation for Activity Recognition on Diverse Domains

K. Peng, D. Wen, D. Schneider, J. Zhang, K. Yang, M. S. Sarfraz, R. Stiefelhagen, A. Roitberg

arXiv preprint 2023

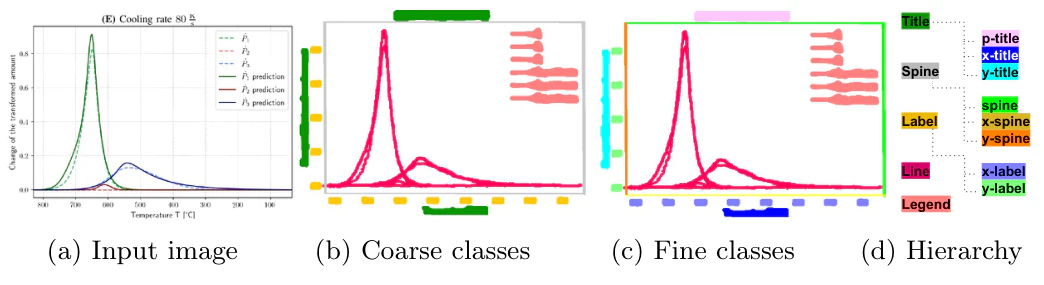
Line Graphics Digitization: A Step Towards Full Automation — research illustration

Line Graphics Digitization: A Step Towards Full Automation

O. Moured, J. Zhang, A. Roitberg, T. Schwarz, R. Stiefelhagen

ICDAR 2023

2022

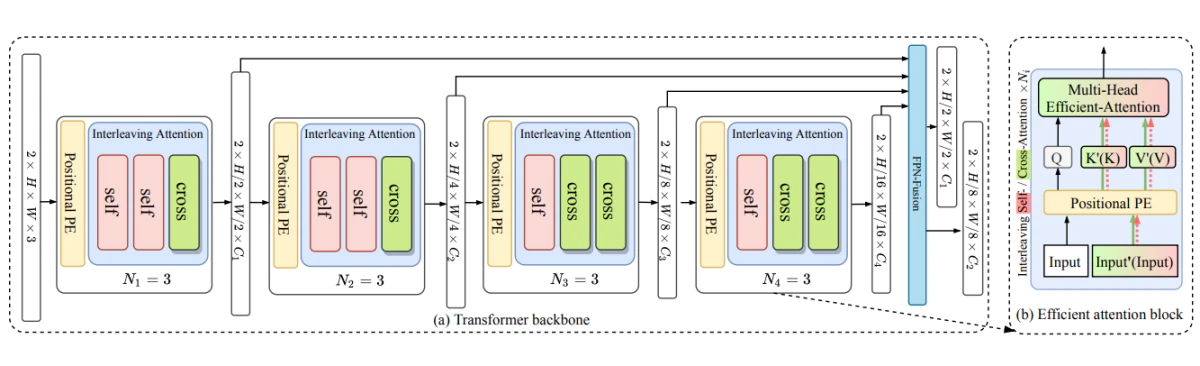
MatchFormer: Interleaving Attention in Transformers for Feature Matching — research illustration

MatchFormer: Interleaving Attention in Transformers for Feature Matching

Q. Wang*, J. Zhang*, K. Yang, K. Peng, R. Stiefelhagen

ACCV 2022

Bending Reality: Distortion-aware Transformers for Adapting to Panoramic Semantic Segmentation — research illustration

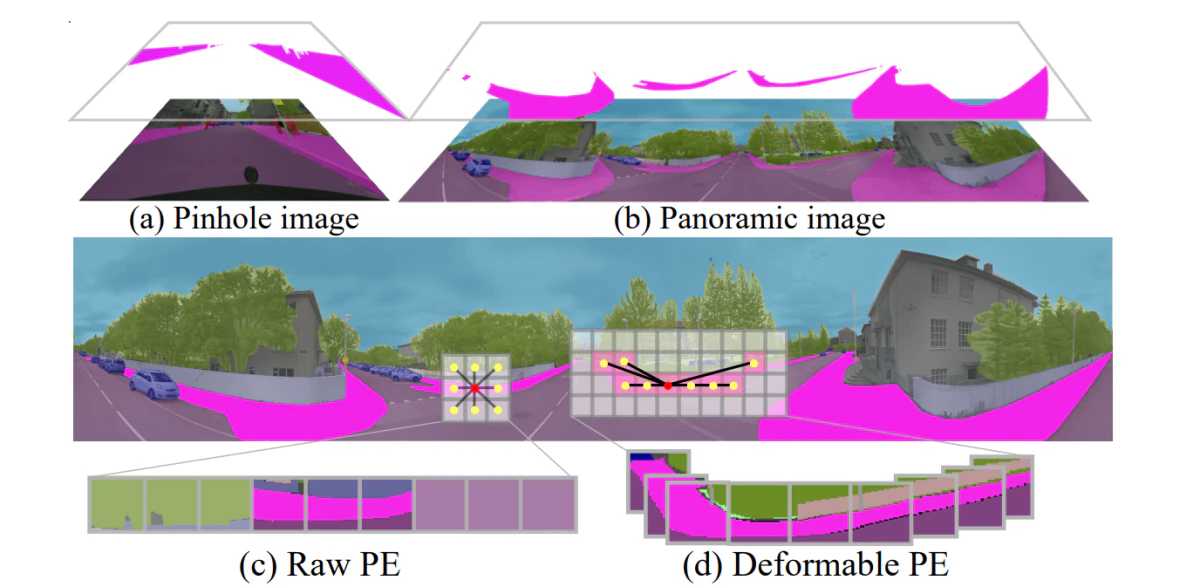
Bending Reality: Distortion-aware Transformers for Adapting to Panoramic Semantic Segmentation

J. Zhang, K. Yang, C. Ma, S. Reiß, K. Peng, R. Stiefelhagen

CVPR 2022

Trans4Trans: Efficient Transformer for Transparent Object and Semantic Scene Segmentation in Real-World Navigation Assistance — research illustration

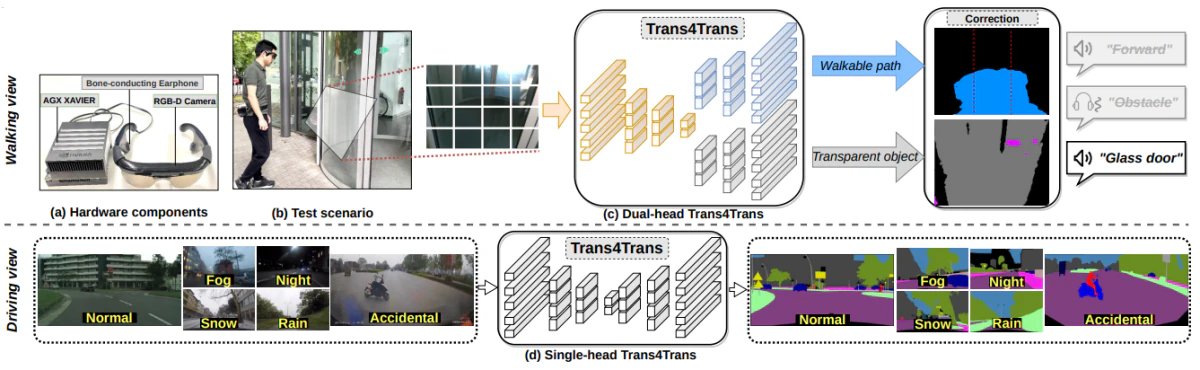
Trans4Trans: Efficient Transformer for Transparent Object and Semantic Scene Segmentation in Real-World Navigation Assistance

J. Zhang, K. Yang, A. Constantinescu, K. Peng, K. Müller, R. Stiefelhagen

IEEE T-ITS 2022

Multi-modal Depression Estimation Based on Sub-attentional Fusion — research illustration

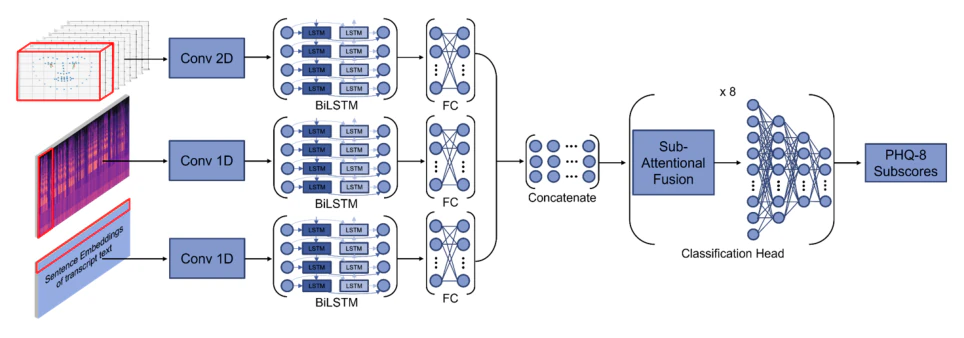
Multi-modal Depression Estimation Based on Sub-attentional Fusion

P.-C. Wei, K. Peng, A. Roitberg, K. Yang, J. Zhang, R. Stiefelhagen

ECCV Workshops (ACVR) 2022

MASS: Multi-Attentional Semantic Segmentation of LiDAR Data for Dense Top-View Understanding — research illustration

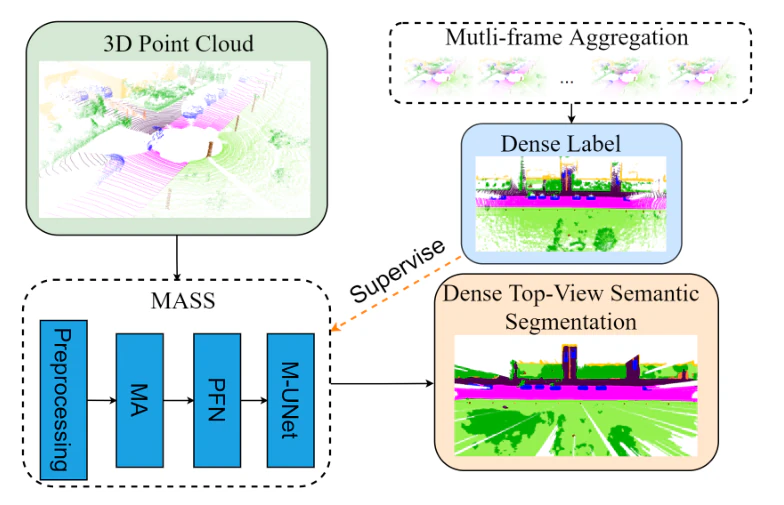
MASS: Multi-Attentional Semantic Segmentation of LiDAR Data for Dense Top-View Understanding

K. Peng, J. Fei, K. Yang, A. Roitberg, J. Zhang, F. Bieder, P. Heidenreich, C. Stiller, R. Stiefelhagen

IEEE T-ITS 2022

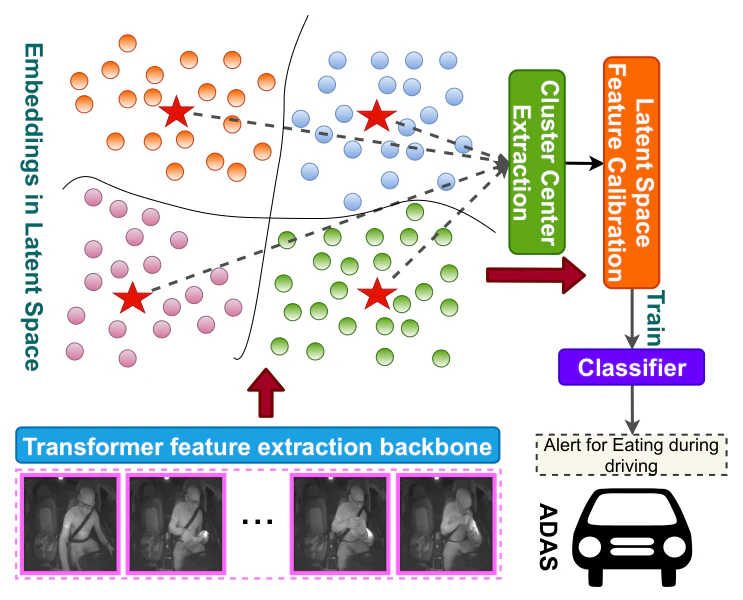
TransDARC: Transformer-Based Driver Activity Recognition with Latent Space Feature Calibration — research illustration

TransDARC: Transformer-Based Driver Activity Recognition with Latent Space Feature Calibration

K. Peng, A. Roitberg, K. Yang, J. Zhang, R. Stiefelhagen

IEEE/RSJ IROS 2022

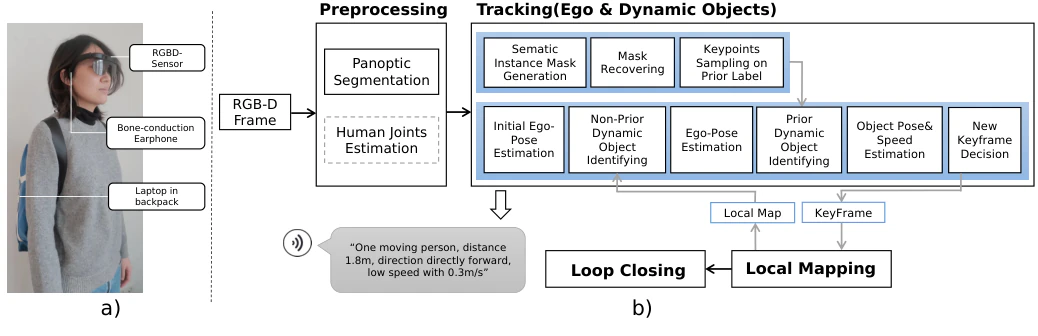
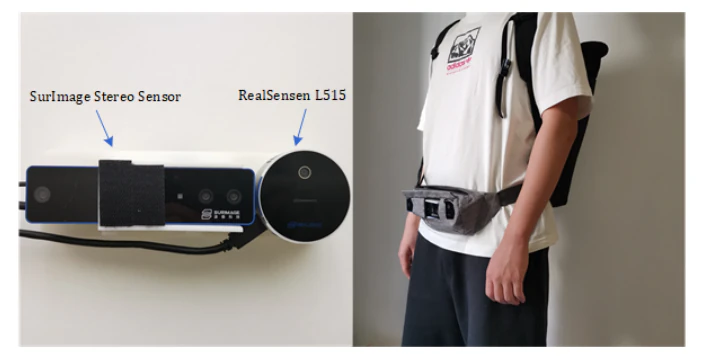
Indoor Navigation Assistance for Visually Impaired People via Dynamic SLAM and Panoptic Segmentation with an RGB-D Sensor — research illustration

Indoor Navigation Assistance for Visually Impaired People via Dynamic SLAM and Panoptic Segmentation with an RGB-D Sensor

W. Ou, J. Zhang, K. Peng, K. Yang, G. Jaworek, K. Müller, R. Stiefelhagen

ICCHP 2022

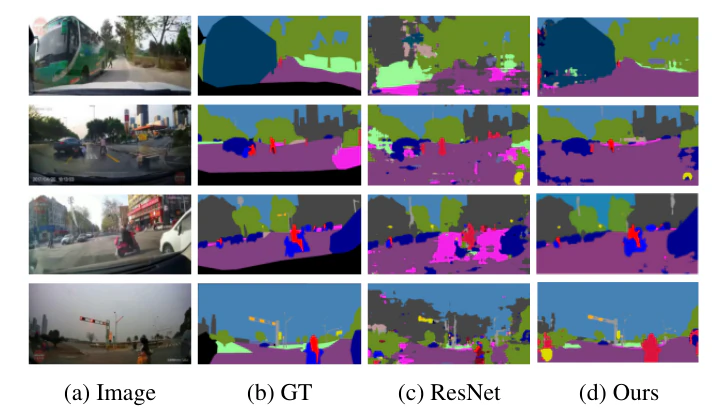
Towards Robust Semantic Segmentation of Accident Scenes via Multi-Source Mixed Sampling and Meta-Learning — research illustration

Towards Robust Semantic Segmentation of Accident Scenes via Multi-Source Mixed Sampling and Meta-Learning

X. Luo, J. Zhang, K. Yang, A. Roitberg, K. Peng, R. Stiefelhagen

CVPR Workshops 2022

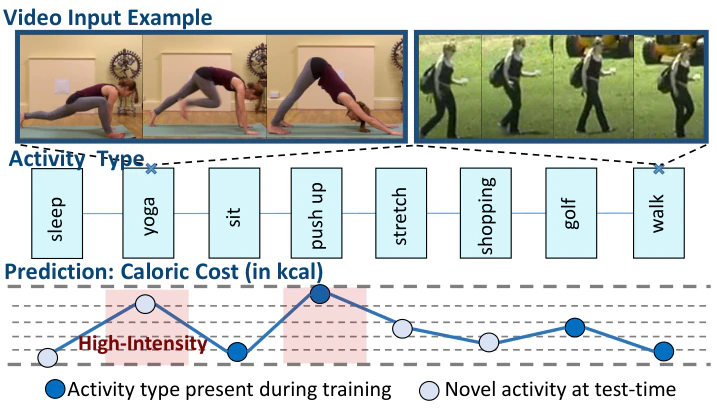
Should I Take a Walk? Estimating Energy Expenditure from Video Data — research illustration

Should I Take a Walk? Estimating Energy Expenditure from Video Data

K. Peng, A. Roitberg, K. Yang, J. Zhang, R. Stiefelhagen

CVPR Workshops (CVPM) 2022

2021

Exploring Event-Driven Dynamic Context for Accident Scene Segmentation — research illustration

Exploring Event-Driven Dynamic Context for Accident Scene Segmentation

J. Zhang, K. Yang, R. Stiefelhagen

IEEE T-ITS 2021

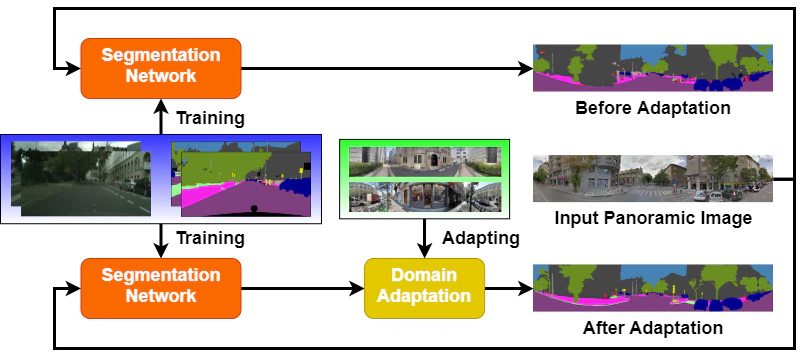
Transfer beyond the Field of View: Dense Panoramic Semantic Segmentation via Unsupervised Domain Adaptation — research illustration

Transfer beyond the Field of View: Dense Panoramic Semantic Segmentation via Unsupervised Domain Adaptation

J. Zhang, C. Ma, K. Yang, A. Roitberg, K. Peng, R. Stiefelhagen

IEEE T-ITS 2021

Capturing Omni-Range Context for Omnidirectional Segmentation — research illustration

Capturing Omni-Range Context for Omnidirectional Segmentation

K. Yang, J. Zhang, S. Reiß, X. Hu, R. Stiefelhagen

CVPR 2021

ISSAFE: Improving Semantic Segmentation in Accidents by Fusing Event-based Data — research illustration

ISSAFE: Improving Semantic Segmentation in Accidents by Fusing Event-based Data

J. Zhang, K. Yang, R. Stiefelhagen

IEEE/RSJ IROS 2021

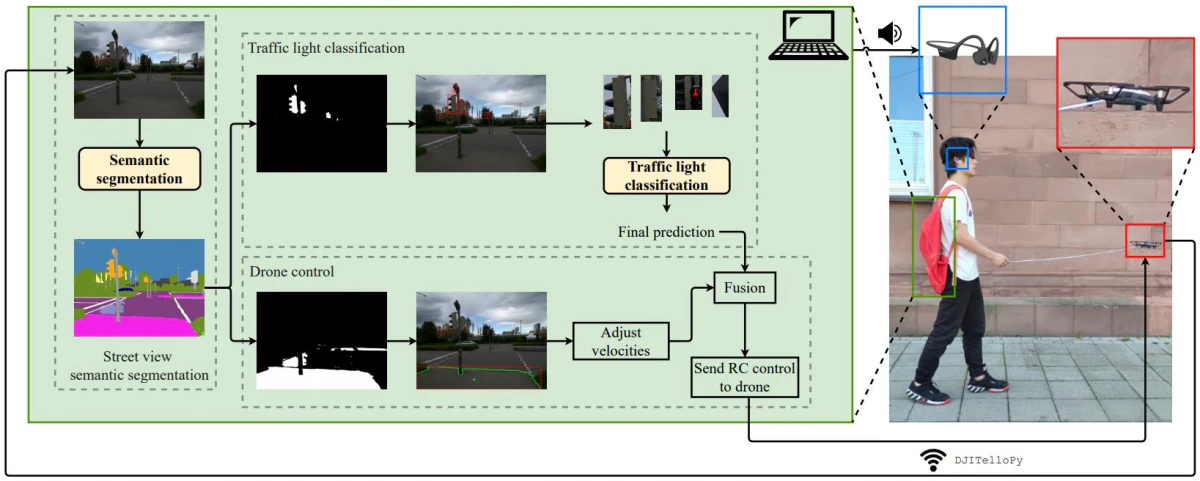
Flying Guide Dog: Walkable Path Discovery for the Visually Impaired Utilizing Drones and Transformer-based Semantic Segmentation — research illustration

Flying Guide Dog: Walkable Path Discovery for the Visually Impaired Utilizing Drones and Transformer-based Semantic Segmentation

H. Tan, C. Chen, X. Luo, J. Zhang, C. Seibold, K. Yang, R. Stiefelhagen

IEEE ROBIO 2021

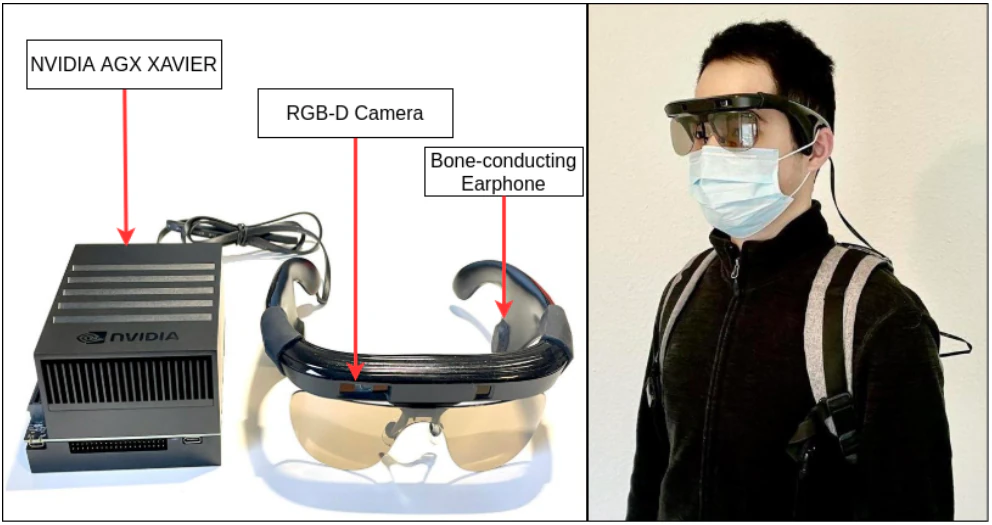
HIDA: Towards Holistic Indoor Understanding for the Visually Impaired via Semantic Instance Segmentation with a Wearable Solid-State LiDAR Sensor — research illustration

HIDA: Towards Holistic Indoor Understanding for the Visually Impaired via Semantic Instance Segmentation with a Wearable Solid-State LiDAR Sensor

H. Liu, R. Liu, K. Yang, J. Zhang, K. Peng, R. Stiefelhagen

ICCV Workshops (ACVR) 2021

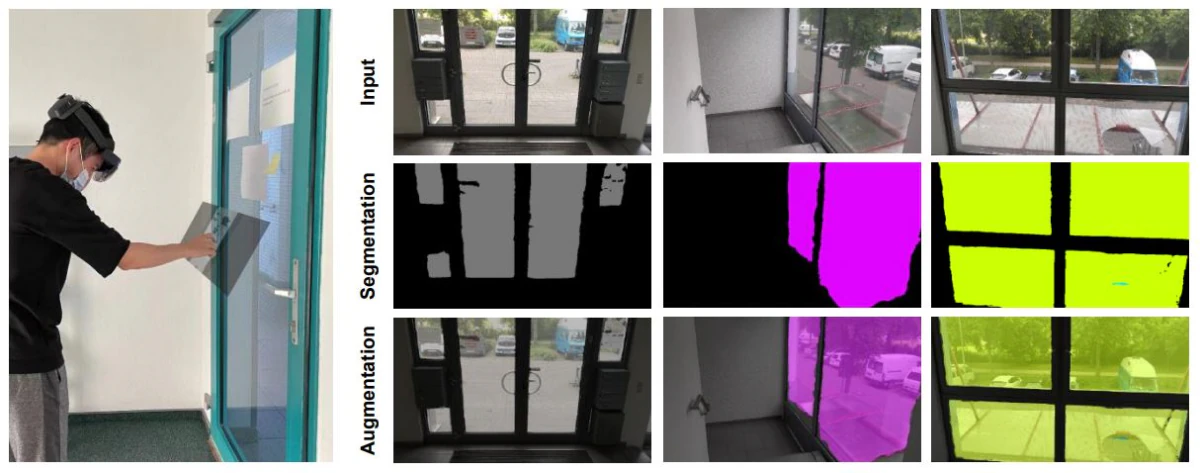
Trans4Trans: Efficient Transformer for Transparent Object Segmentation to Help Visually Impaired People Navigate in the Real World — research illustration

Trans4Trans: Efficient Transformer for Transparent Object Segmentation to Help Visually Impaired People Navigate in the Real World

J. Zhang, K. Yang, A. Constantinescu, K. Peng, K. Müller, R. Stiefelhagen

ICCV Workshops (ACVR) 2021

DensePASS: Dense Panoramic Semantic Segmentation via Unsupervised Domain Adaptation with Attention-Augmented Context Exchange — research illustration

DensePASS: Dense Panoramic Semantic Segmentation via Unsupervised Domain Adaptation with Attention-Augmented Context Exchange

C. Ma, J. Zhang, K. Yang, A. Roitberg, R. Stiefelhagen

IEEE ITSC 2021

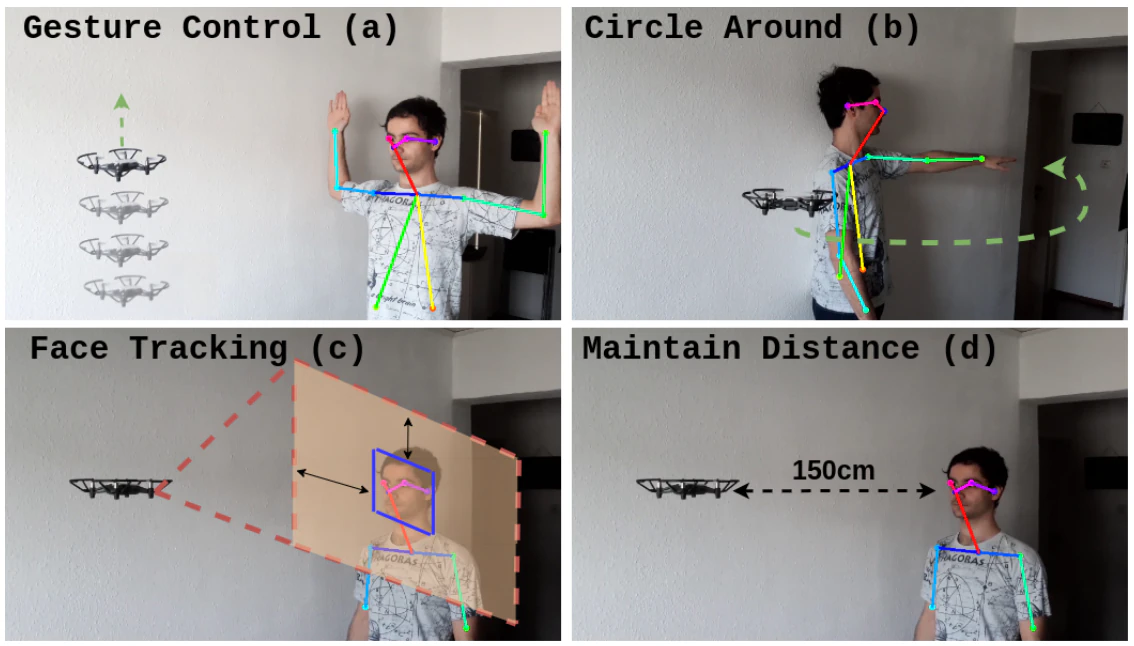
Pose2Drone: A Skeleton-Pose-based Framework for Human-Drone Interaction — research illustration

Pose2Drone: A Skeleton-Pose-based Framework for Human-Drone Interaction

Z. Marinov, S. Vasileva, Q. Wang, C. Seibold, J. Zhang, R. Stiefelhagen

IEEE EUSIPCO 2021

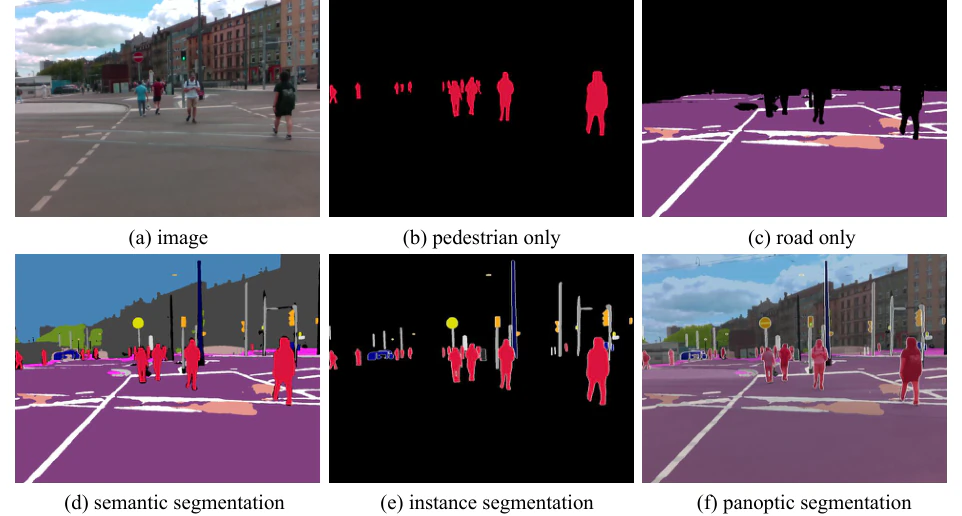
Panoptic Lintention Network: Towards Efficient Navigational Perception for the Visually Impaired — research illustration

Panoptic Lintention Network: Towards Efficient Navigational Perception for the Visually Impaired

W. Mao*, J. Zhang*, K. Yang, R. Stiefelhagen

IEEE RCAR 2021

Perception Framework through Real-Time Semantic Segmentation and Scene Recognition on a Wearable System for the Visually Impaired — research illustration

Perception Framework through Real-Time Semantic Segmentation and Scene Recognition on a Wearable System for the Visually Impaired

Y. Zhang, H. Chen, K. Yang, J. Zhang, R. Stiefelhagen

IEEE RCAR 2021

2020

Can We Cover Navigational Perception Needs of the Visually Impaired by Panoptic Segmentation? — research illustration

Can We Cover Navigational Perception Needs of the Visually Impaired by Panoptic Segmentation?

W. Mao, J. Zhang, K. Yang, R. Stiefelhagen

arXiv preprint 2020